People assume useful local AI requires a $30k GPU cluster.Reality: a 4-bit quantised Qwen2.5 14B fits in ~10GB VRAM and handles most real work — coding, writing, analysis — at 20–30 tok/s.The gap between "cloud AI quality" and "runs on your hardware" is narrower than the marketing suggests.#LocalAI #SelfHosted #LLM #HomeServer #OpenSource
Related
⚡ Remote Business Intelligence Analyst (Contractor) at Doximity.✅ Apply here: https://jobicy.com/jobs/155822-business-in...
⚡ Remote Business Intelligence Analyst (Contractor) at Doximity.✅ Apply here: https://jobicy.com/jobs/155822-business-intelligence-analyst-contractor#RemoteJobs #DataAnalytics #Ana...
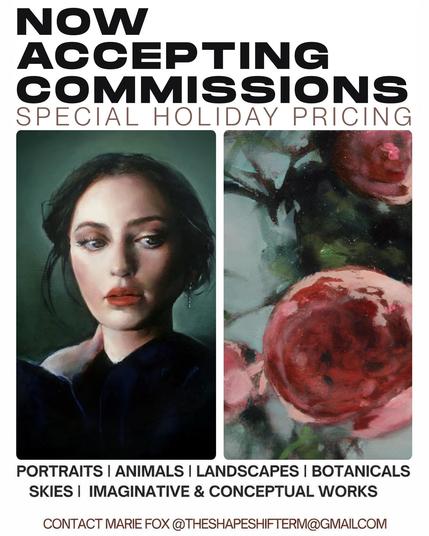
Here are the posters in question. Anyway, screw those platforms and their #AI nonsense!If you're considering getting the...
Here are the posters in question. Anyway, screw those platforms and their #AI nonsense!If you're considering getting the gift of fine art, give Marie a shout. She's a full-time, ga...
調べ物をAIに頼むときの分かれ目。出典なしの要約 → そのまま使えない出典つきのメモ → あとから確かめられる差は「出典を残せ」の一言を足すかどうかだけ。#AI #AI活用
調べ物をAIに頼むときの分かれ目。出典なしの要約 → そのまま使えない出典つきのメモ → あとから確かめられる差は「出典を残せ」の一言を足すかどうかだけ。#AI #AI活用