Token budgeting, fallback models, and caching strategies that cut LLM API bills. With real numbers, hardware break-even analysis, and working Python code.#LLM #AI #Cost Optimization #Local Inferencehttps://www.glukhov.org/llm-architecture/cost-optimization/cost-optimization-for-llm-systems/
Related
⚡ Remote Business Intelligence Analyst (Contractor) at Doximity.✅ Apply here: https://jobicy.com/jobs/155822-business-in...
⚡ Remote Business Intelligence Analyst (Contractor) at Doximity.✅ Apply here: https://jobicy.com/jobs/155822-business-intelligence-analyst-contractor#RemoteJobs #DataAnalytics #Ana...
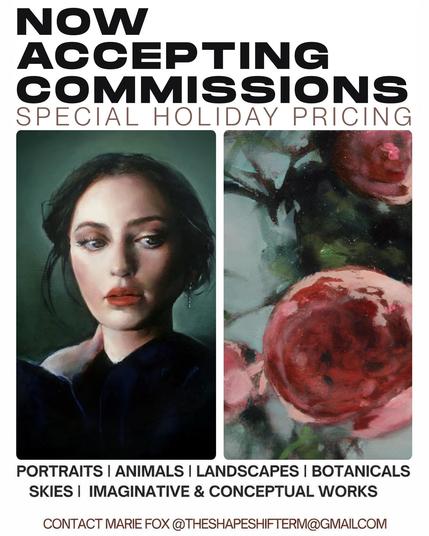
Here are the posters in question. Anyway, screw those platforms and their #AI nonsense!If you're considering getting the...
Here are the posters in question. Anyway, screw those platforms and their #AI nonsense!If you're considering getting the gift of fine art, give Marie a shout. She's a full-time, ga...
調べ物をAIに頼むときの分かれ目。出典なしの要約 → そのまま使えない出典つきのメモ → あとから確かめられる差は「出典を残せ」の一言を足すかどうかだけ。#AI #AI活用
調べ物をAIに頼むときの分かれ目。出典なしの要約 → そのまま使えない出典つきのメモ → あとから確かめられる差は「出典を残せ」の一言を足すかどうかだけ。#AI #AI活用