UC San Diego researchers have developed DFlash, a block diffusion model that drafts whole token blocks in a single pass for speculative decoding. The technique delivers up to 15x higher throughput on NVIDIA Blackwell GPUs compared to traditional autoregressive methods. It works by having a small draft model propose token blocks that the larger target model verifies in parallel, making AI inference significantly faster for coding agents and reasoning models. https://www.marktechpost.com/2026/06/24/dflash-speculative-decoding-drafts-whole-token-blocks-in-parallel-for-up-to-15x-higher-throughput-on-nvidia-blackwell/ #AIagent #AI #GenAI #AIInfrastructure
Related
MiniMax has open-weighted H3-Image, a 33.1 billion parameter diffusion transformer for text-to-image and editing, produc...
MiniMax has open-weighted H3-Image, a 33.1 billion parameter diffusion transformer for text-to-image and editing, producing roughly 16 megapixel output at 4096 by 4096 in under 10 ...
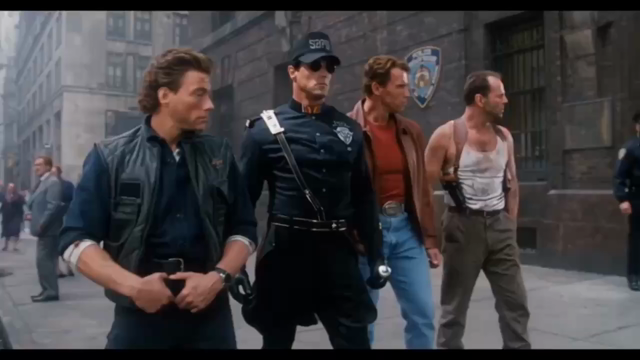
All the heroes.Credit to the creator.#heroes #ai
All the heroes.Credit to the creator.#heroes #ai
AI-Powered Analysis Reveals Hidden Phishing Chains in PDF Attackshttps://www.dwc.news/posts/ai-powered-analysis-reveals-...
AI-Powered Analysis Reveals Hidden Phishing Chains in PDF Attackshttps://www.dwc.news/posts/ai-powered-analysis-reveals-hidden-phishing-chains-in-pdf-attacks-261111#phishing #AI #S...