Am I in The Stack V3, https://huggingface.co/spaces/HuggingFaceCode/in-the-stack.> The Stack v3 is a 15.9 TB dataset of source code across 713 programming languages from 173M repositories, crawled from GitHub in 2025ALL my projects have been used to train this model. All of them. Including orgs I contribute to.…What if an LLM generates code from my PhD thesis, or any algorithms I wrote? Good luck with the copyrights.#llm #ai
Related
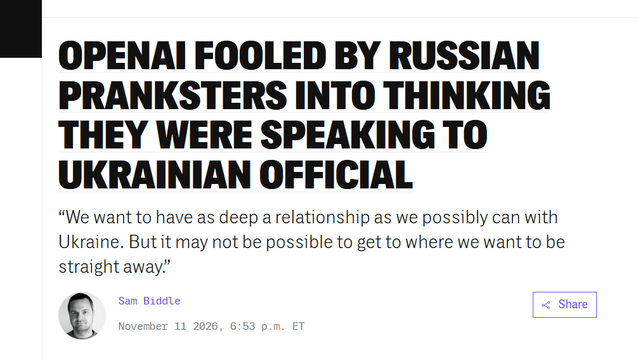
"A Russian internet comedy duo tricked three of OpenAI’s highest ranking military and national security staff into a can...
"A Russian internet comedy duo tricked three of OpenAI’s highest ranking military and national security staff into a candid conversation about arming Ukraine. The online pranksters...
The newest AI models can do amazing things. It is however good to remember the costs are also extreme. This video shows ...
The newest AI models can do amazing things. It is however good to remember the costs are also extreme. This video shows some amazing examples but includes the time it took to build...
I write about ML, Python, and occasionally zombies. It's a range.The blog covers practical stuff like pytest patterns an...
I write about ML, Python, and occasionally zombies. It's a range.The blog covers practical stuff like pytest patterns and clustering in Python alongside weirder pieces on the uncan...