📊 Qwen3 235B A22B (Reasoning) — the actual numbers GPQA: 70% MMLU-Pro: 82.8% Humanity's Last Exam: 11% Long Context Reasoning: 0%💰 5.1 intelligence points per dollarMeasured independently, not self-reported →https://olud.ai/leaderboard.html#LLM #Benchmarks #OpenSource #AI
Related
“Been seeing a lot more #outages amongst the big tech companies in the last year. I have suspicions this is cause of mor...
“Been seeing a lot more #outages amongst the big tech companies in the last year. I have suspicions this is cause of more bad and insecure #AIgenerated #code being pushed into code...
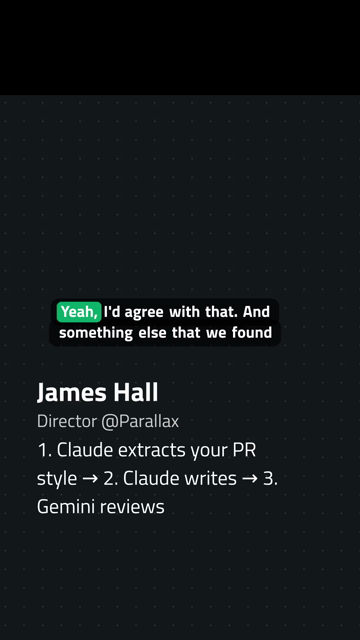
Don't let the same LLM write and review your code.→ Claude analyzes your last 1,000 PRs to build a team style guide, the...
Don't let the same LLM write and review your code.→ Claude analyzes your last 1,000 PRs to build a team style guide, then writes the code. → Gemini takes over code review and enfor...
Tools like Clipto now allow ChatGPT and Claude to search years of meeting recordings, changing how engineering teams lev...
Tools like Clipto now allow ChatGPT and Claude to search years of meeting recordings, changing how engineering teams leverage institutional knowledge. The core trade-off centers on...