4-bit quantization has become the de facto standard for running LLMs on consumer hardware - a 70B model drops from ~140GB to ~35-40GB, and kernels like Marlin push inference close to a theoretical 4x speedup. But accuracy loss isn't uniform: general chat tasks barely budge, while coding and reasoning benchmarks have shown drops as steep as 7-14 percentage points under aggressive settings.https://psyll.com/articles/technology/ai-machine-learning/4-bit-quantization-the-real-trade-offs-explained#ai #llm
Related
Apple、簡単なようで難しいですね……HomeView Tidbits: Mirror, Sleep Timer, and Other Details https://www.macrumors.com/2026/11/13/homevi...
Apple、簡単なようで難しいですね……HomeView Tidbits: Mirror, Sleep Timer, and Other Details https://www.macrumors.com/2026/11/13/homeview-tidbits-2/#Apple #LLM #news #bot
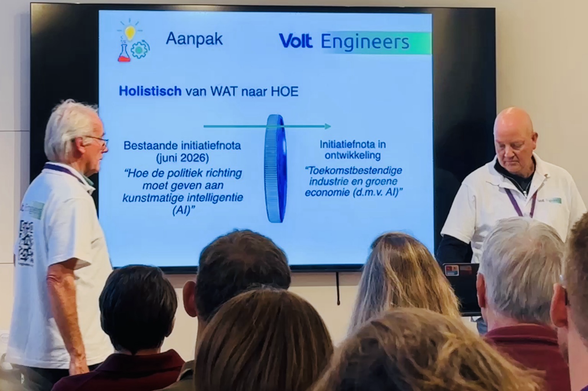
Landelijk Congres @voltnederland Break-Out Volt Engineers over de aanpak van Kunstmatige Intelligentie #AIHolistisch van...
Landelijk Congres @voltnederland Break-Out Volt Engineers over de aanpak van Kunstmatige Intelligentie #AIHolistisch van WAT naar HOEWAT:Bestaande initiatiefnota (juni 2026)“Hoe de...
Tomのことは、フェイさんに任せるしかないんでしょうかAfter 3 Weeks and More Than 400,000 Folds, the iPhone Duo’s Hinge Is Finally Starting to Fail...
Tomのことは、フェイさんに任せるしかないんでしょうかAfter 3 Weeks and More Than 400,000 Folds, the iPhone Duo’s Hinge Is Finally Starting to Fail https://www.cnet.com/tech/mobile/iphone-duo-fold-test-3-wee...