New benchmark MSEval shows multi-agent coding outcomes depend as much on team topology as model strength, with topology shifts altering scores by over 30 points and doubling runtime.Source: arXiv cs.MAhttps://arxiv.org/abs/2607.27877#MachineLearning
Related
“Been seeing a lot more #outages amongst the big tech companies in the last year. I have suspicions this is cause of mor...
“Been seeing a lot more #outages amongst the big tech companies in the last year. I have suspicions this is cause of more bad and insecure #AIgenerated #code being pushed into code...
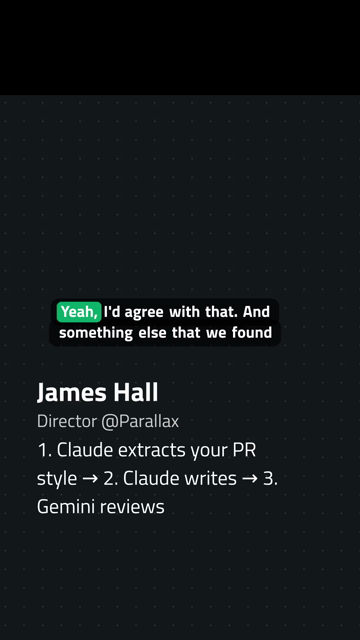
Don't let the same LLM write and review your code.→ Claude analyzes your last 1,000 PRs to build a team style guide, the...
Don't let the same LLM write and review your code.→ Claude analyzes your last 1,000 PRs to build a team style guide, then writes the code. → Gemini takes over code review and enfor...
Tools like Clipto now allow ChatGPT and Claude to search years of meeting recordings, changing how engineering teams lev...
Tools like Clipto now allow ChatGPT and Claude to search years of meeting recordings, changing how engineering teams leverage institutional knowledge. The core trade-off centers on...