We are quickly arriving at the time where we can run models on local hardware that rival some of the largest datacenter based models from a few months ago. A lot of companies will start building and using these in their own infrastructure to provide cheap local AI services instead of expensive BigTech APIs.https://simonwillison.net/2026/Aug/16/qwen-38-27b/#AI #Qwen38 #local #LLM
Related
🌟 Spotted today #CodeTrendy → TiquizAI quiz funnels that tag leads in Systeme.io & GoHighLevel#EmailMarketing #AI #Email...
🌟 Spotted today #CodeTrendy → TiquizAI quiz funnels that tag leads in Systeme.io & GoHighLevel#EmailMarketing #AI #Email #Bootstrapped #Nextjs #Supabase #ChatGPTOpenAIhttps://codet...
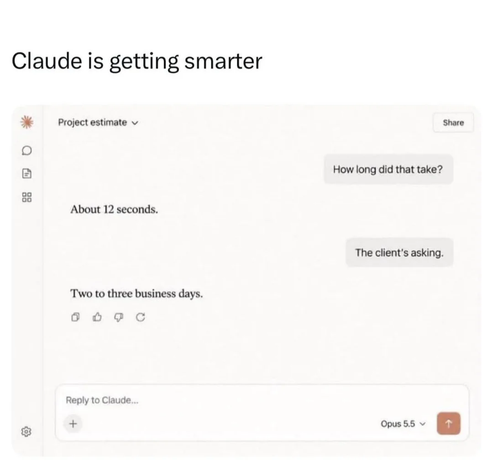
Lol, but hopefully this will help some of you that face issues with managers asking Claude for how long your work is sup...
Lol, but hopefully this will help some of you that face issues with managers asking Claude for how long your work is supposed to take:#Claude #AI
Paul Krugman questions if an artificial intelligence bubble could soon crash the global economy. His latest analysis dra...
Paul Krugman questions if an artificial intelligence bubble could soon crash the global economy. His latest analysis draws clear parallels to dot-com era excesses through enormous ...