Embedding workloads can look healthy on latency dashboards while changing retrieval quality after a hardware move. Google's vLLM TPU implementation preserves pooling state across chunked prefill and validates cosine similarity against reference outputs. That is the right release shape: benchmark speed, but gate deployment on numerical parity.https://developers.googleblog.com/enterprise-grade-precision-for-long-context-multimodal-embedding-inference-on-cloud-tpu/#MachineLearning #MLOps
Related
🌟 Spotted today #CodeTrendy → TiquizAI quiz funnels that tag leads in Systeme.io & GoHighLevel#EmailMarketing #AI #Email...
🌟 Spotted today #CodeTrendy → TiquizAI quiz funnels that tag leads in Systeme.io & GoHighLevel#EmailMarketing #AI #Email #Bootstrapped #Nextjs #Supabase #ChatGPTOpenAIhttps://codet...
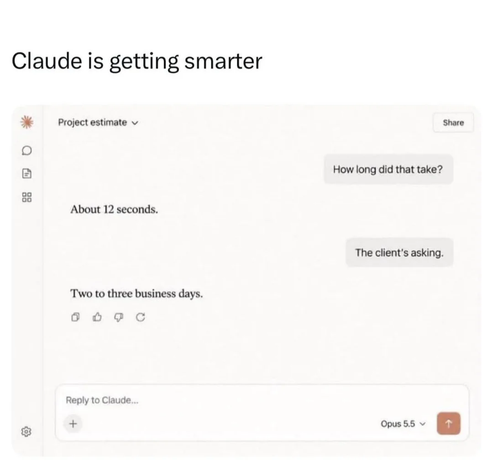
Lol, but hopefully this will help some of you that face issues with managers asking Claude for how long your work is sup...
Lol, but hopefully this will help some of you that face issues with managers asking Claude for how long your work is supposed to take:#Claude #AI
Paul Krugman questions if an artificial intelligence bubble could soon crash the global economy. His latest analysis dra...
Paul Krugman questions if an artificial intelligence bubble could soon crash the global economy. His latest analysis draws clear parallels to dot-com era excesses through enormous ...