Anthropic’s automated alignment researchers improved 10 measured failure modes and generalized to held-out tests. The deeper result: automation is useful only when humans design a non-gameable evaluation portfolio. Single-benchmark gains mostly failed to transfer.https://www.anthropic.com/research/automated-researchers-mitigate-alignment-failures #AI #Evaluation
Related
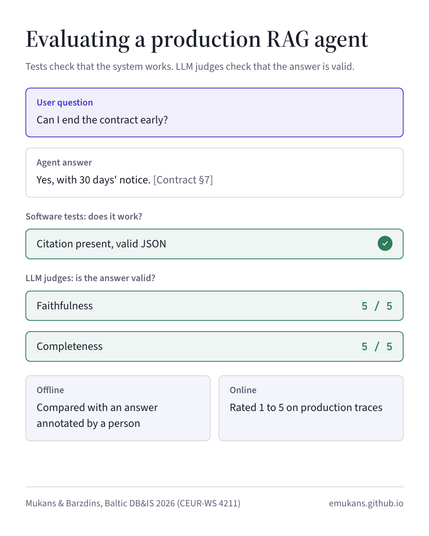
After a change to a RAG system, the answers still read fluently. Whether they got better or worse is another matter: "Th...
After a change to a RAG system, the answers still read fluently. Whether they got better or worse is another matter: "The contract cannot be terminated with 30 days' notice" shares...
Ich fahre sehr viel mit der Bahn und heute passen die Angaben in der App gar nicht. Gestern stimmte die Abfahrtszeit nic...
Ich fahre sehr viel mit der Bahn und heute passen die Angaben in der App gar nicht. Gestern stimmte die Abfahrtszeit nicht und meinem Sohn und mir wurden nicht die gleichen Züge an...
OpenAI third-quarter revenue reaches $10 billion, up nearly 50%OpenAI's quarterly revenue hit $10 billion for the first ...
OpenAI third-quarter revenue reaches $10 billion, up nearly 50%OpenAI's quarterly revenue hit $10 billion for the first time in the three months ending in September, up nearly 50% ...