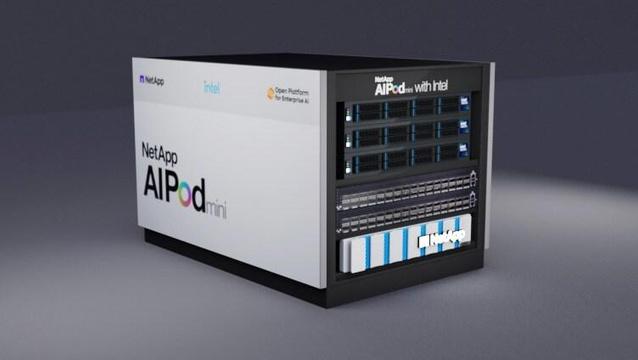
What's actually slower in your AI stack — GPU compute, or getting the data to it? For a 1 PB corpus of docs and parquet shards it's the pipeline: millions of small files hammer the metadata path, and generic NAS stalls before a single GPU spins up. ONTAP AFF handles that layer — and NetApp's Intelligent Data Infrastructure pitch is really about this, not the GPU rack. #NetApp #ONTAP #AI #Storage #DataPipeline
What's actually slower in your AI stack — GPU compute, or getting the data to it? For a 1 PB corpus of docs and parquet ...