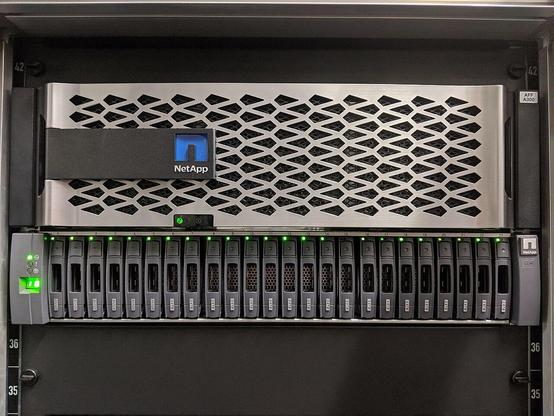
Nobody buys storage for AI because of the training run — they buy it for the checkpoint. A multi-thousand-GPU job writes tens of TB in minutes on a fixed cadence, and every stall waiting on disk is GPU-hours burned. Parallel filesystems and NVMe tiers exist to make checkpoint/restore boring; when it isn't, recovery time becomes your real training tax.#AI #Storage #Checkpoint #HPC #NetApp
Nobody buys storage for AI because of the training run — they buy it for the checkpoint. A multi-thousand-GPU job writes...