OpenAI's Astra scored 99.9% on its own benchmark, but ARC Prize—which built the test—scored the same model at 62.7% on a neutral harness. The 37-point gap raises a procurement question: which evaluation do you trust? #AI #Benchmarking #Evidence https://www.implicator.ai/astras-agi-benchmark-reads-99-9-or-62-7-g-20-backs-lighter-ai-rules/
Related
#GroundStop #FAA #AI‘AI departing traffic should remain groundstopped until further notice.'
#GroundStop #FAA #AI‘AI departing traffic should remain groundstopped until further notice.'
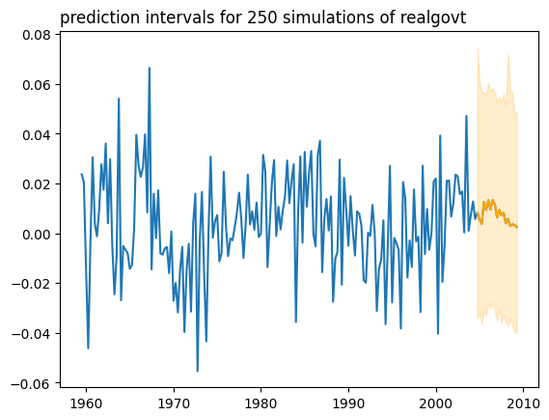
You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTShttps://thierrymoudiki.g...
You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTShttps://thierrymoudiki.github.io/blog/2024/11/24/r/python/forecasting/nnetsauce/nnet...
Simon Willisons llm-CLI konnte euren OpenAI-Key an fremde Endpunkte schicken, ohne Warnung. Version 0.37.2 behebt das. W...
Simon Willisons llm-CLI konnte euren OpenAI-Key an fremde Endpunkte schicken, ohne Warnung. Version 0.37.2 behebt das. Wer eigene api_base-Modelle eingetragen hat, sollte prüfen un...