Notes on the Fable 5.1 benchmark table, read with its footnotes: the standard error on those runs is 3.5 to 4.5 points, so most of the gap over Opus 5 sits inside the noise. The rows left out of the graphic are the ones Opus 5 wins, ARC-AGI-2 at 90.42 against 90.0 and SWE-bench Multimodal at 59.4 against 54.7. https://www.youtube.com/watch?v=azLxlz5FrH8#Anthropic #AICoding #LLM
Related
#GroundStop #FAA #AI‘AI departing traffic should remain groundstopped until further notice.'
#GroundStop #FAA #AI‘AI departing traffic should remain groundstopped until further notice.'
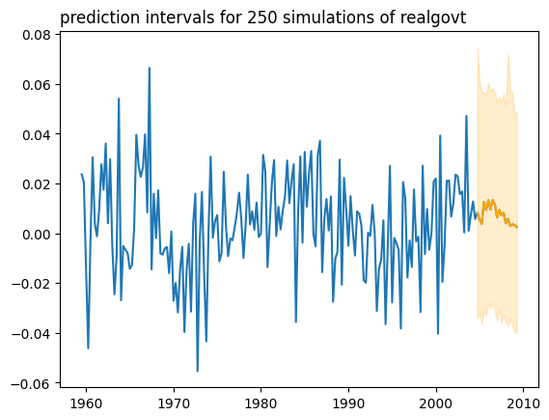
You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTShttps://thierrymoudiki.g...
You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTShttps://thierrymoudiki.github.io/blog/2024/11/24/r/python/forecasting/nnetsauce/nnet...
Simon Willisons llm-CLI konnte euren OpenAI-Key an fremde Endpunkte schicken, ohne Warnung. Version 0.37.2 behebt das. W...
Simon Willisons llm-CLI konnte euren OpenAI-Key an fremde Endpunkte schicken, ohne Warnung. Version 0.37.2 behebt das. Wer eigene api_base-Modelle eingetragen hat, sollte prüfen un...