Grok 4.6 Scores 26% and 88% on the Same Benchmark LinexAI's own model card reports Terminal-Bench 3.0 at 26.0%. Artificial Analysis reports 88.4% on 2.1. Both are the same model. The model card is unusually honest about why — the problem is everyone quoting it drops the qualifiers.https://pickuma.com/for-dev/grok-46-benchmark-versions-thinking-effort/?utm_source=mastodon-mastodon.social&utm_medium=crosspost&utm_campaign=blog#AI #WebDev
Related
#GroundStop #FAA #AI‘AI departing traffic should remain groundstopped until further notice.'
#GroundStop #FAA #AI‘AI departing traffic should remain groundstopped until further notice.'
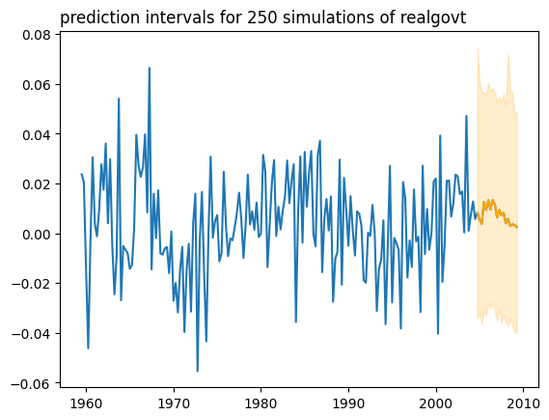
You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTShttps://thierrymoudiki.g...
You can beat Forecasting LLMs (Large Language Models a.k.a foundation models) with nnetsauce.MTShttps://thierrymoudiki.github.io/blog/2024/11/24/r/python/forecasting/nnetsauce/nnet...
Simon Willisons llm-CLI konnte euren OpenAI-Key an fremde Endpunkte schicken, ohne Warnung. Version 0.37.2 behebt das. W...
Simon Willisons llm-CLI konnte euren OpenAI-Key an fremde Endpunkte schicken, ohne Warnung. Version 0.37.2 behebt das. Wer eigene api_base-Modelle eingetragen hat, sollte prüfen un...