NVIDIA stellt Qwen3.8-27B als NVFP4/FP8-Quantisierung vor. Die Mixed-Precision-Variante nutzt Model Optimizer v0.48.0 und erreicht auf Grace Blackwell GB300 mit vLLM nahezu BF16-Genauigkeit bei Agenten- und Multimodal-Tasks. Apache-2.0-Lizenz, 262K Kontext.https://huggingface.co/nvidia/Qwen3.8-27B-NVFP4#KI #AI #LLM #AISyndicate
Related
Your server logs say GPTBot visited. Did it?A user-agent string is just text: anyone can send "GPTBot" or "PerplexityBot...
Your server logs say GPTBot visited. Did it?A user-agent string is just text: anyone can send "GPTBot" or "PerplexityBot". Before you decide which AI bots reach your site, verify t...
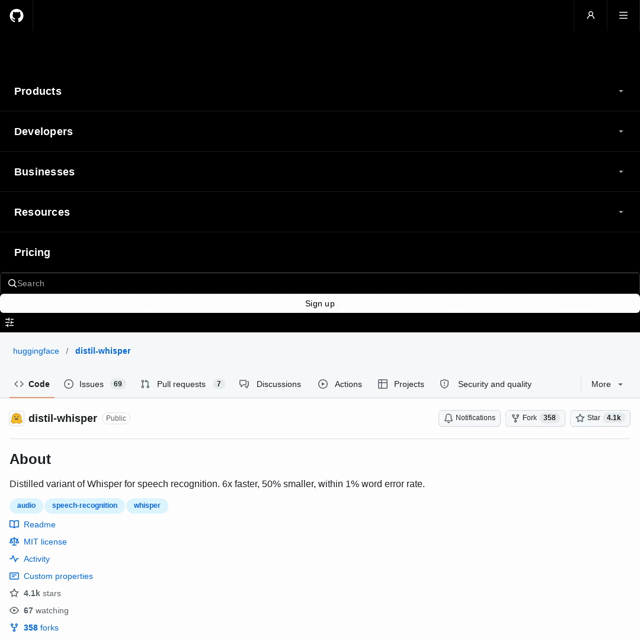
💻 distil-whisper: 4.1 k ⭐Knowledge distillation doing what it does best.Hugging Face's distil-whisper takes OpenAI's Whi...
💻 distil-whisper: 4.1 k ⭐Knowledge distillation doing what it does best.Hugging Face's distil-whisper takes OpenAI's Whisper and compresses it to 756M params (down from 1.55B), del...
With LLMs trivially finding 0-day exploits in widely deployed software stacks, _security by obscurity_ becomes a viable ...
With LLMs trivially finding 0-day exploits in widely deployed software stacks, _security by obscurity_ becomes a viable defence mechanism.(followed by SELinux+FApolicy+AIDE of cour...