This post was created with AI assistance and reviewed for accuracy before publishing.Rate limiting a normal API protects your servers. Rate limiting an LLM API protects your bank account. The difference matters, because it changes what you are counting and where the limit has to live.A conventional web endpoint costs you CPU time measured in milliseconds. A single model call can cost real money, and an agent loop can issue hundreds of them without a human ever clicking anything. One customer leaving a misconfigured retry loop running overnight is a bill, not a blip. Count tokens, not just requestsThe instinct is to limit requests per minute. That is necessary but not sufficient, because requests vary in cost by three orders of magnitude. A one-line prompt and a 200-page document summarisation are both "one request".Track both, and enforce whichever binds first:// Two windows, different units, same tenant.await Promise.all([ consume(`rl:${tenantId}:req`, 1, 60), // 60 requests / minute ...
Related
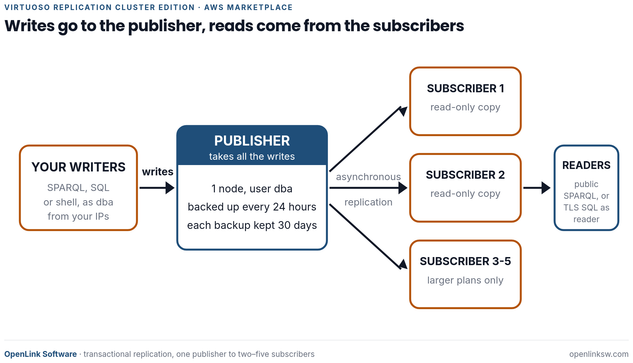
When your data, information, and knowledge must stay available, replication matters.Virtuoso Replication Cluster Edition...
When your data, information, and knowledge must stay available, replication matters.Virtuoso Replication Cluster Edition gives you transactional replication with one publisher serv...
DeepSeek has opened the main features of its app as APIs, letting developers rebuild web search, file parsing, OCR, spee...
DeepSeek has opened the main features of its app as APIs, letting developers rebuild web search, file parsing, OCR, speech recognition and synthesis in their own products. The deep...
Egyptian potato exporter deploys ORTH AI across 54,000 acres.DALTEX announced the deployment of ORTH’s artificial - inte...
Egyptian potato exporter deploys ORTH AI across 54,000 acres.DALTEX announced the deployment of ORTH’s artificial - intelligence platform across its Egyptian potato - farming opera...