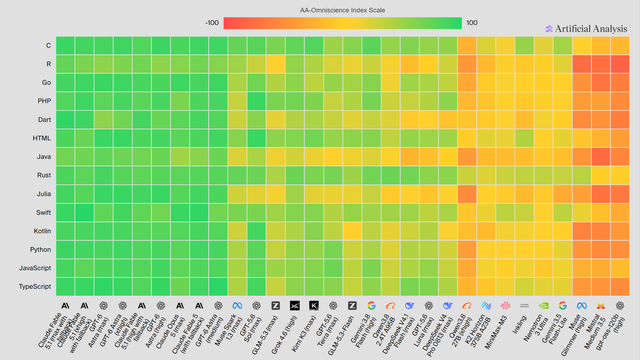
Okay, the breakdown *by-language* of Artificial Analysis's "Omniscience" hallucination/capability benchmark is absolutely fascinating.I feel like this is some of the first concrete evidence I've seen of my longtime lean: that the *correctness* tooling we obsess over in PLT spaces is one of the greatest possible value-adds to the LLM era. (Just look at the Rust row, holy shit.)Choosing a good language basically shifts the quality of output by an entire cost-category / order-of-magnitude; compare the "R / Astra" cell vs. the "Rust/Luna" cell.https://artificialanalysis.ai/evaluations/omniscience?swe-deep-dive=omniscience-index-across-languages#software-engineering-deep-dive #AI #slop #LLM #typesystems #PLT
Okay, the breakdown *by-language* of Artificial Analysis's "Omniscience" hallucination/capability benchmark is absolutel...