NVIDIA veröffentlicht DeepSeek-V4.1-Flash als NVFP4-Quantisierung (W4A4) für Blackwell-Hardware. Das multimodale MoE-Modell nutzt Compressed Sparse Attention 2 und unterstützt 1M-Token-Kontext. Deployment erfordert vier GB300 GPUs via SGLang oder vLLM.https://huggingface.co/nvidia/DeepSeek-V4.1-Flash-NVFP4#KI #AI #LLM #AISyndicate
Related
----------------🎯 AI: ARTEX and AI-enabled penetration testing frameworks===================Cisco Talos reports in-the-w...
----------------🎯 AI: ARTEX and AI-enabled penetration testing frameworks===================Cisco Talos reports in-the-wild use of AI-enabled penetration testing frameworks, includ...
Please, devs, stop subjecting your users to #AI-generated readmes. They SUCK. They are useless, are awful to read and si...
Please, devs, stop subjecting your users to #AI-generated readmes. They SUCK. They are useless, are awful to read and signal a lack of effort and care that I can only assume extend...
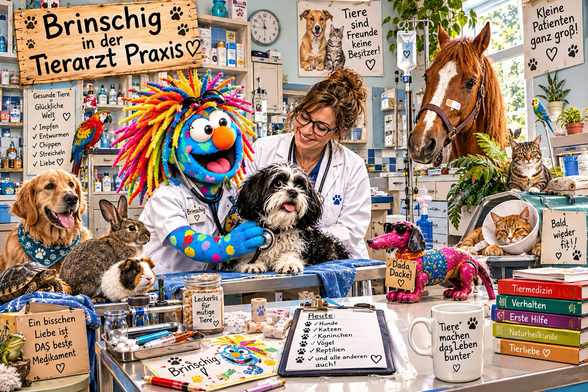
WimmelbildA Brinschig WorldAt the vet‘s (2nd)Meister Jeder, Dadaist und Brinschigmacher 11/26#dada #Brinschig #Puppet #K...
WimmelbildA Brinschig WorldAt the vet‘s (2nd)Meister Jeder, Dadaist und Brinschigmacher 11/26#dada #Brinschig #Puppet #Klappmaul #AI