📊 Llama 3.1 Tulu3 405B’s independent benchmark run: GPQA 51.6%, MMLU-Pro 71.6%, HLE 3.3%, LiveCodeBench 29.1%. The gap between reasoning and coding tells the real story — see how it stacks up on the full leaderboard.https://olud.ai/leaderboard.html#LLM #Benchmarks #OpenSource #AI
Related
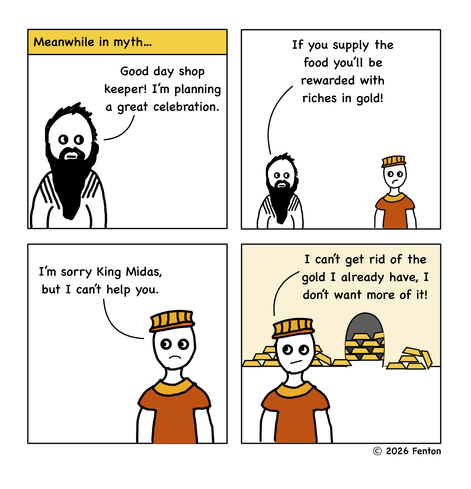
Meanwhile in DevOps No.93.The Midas touch (a story of AI).#MWID #AI
Meanwhile in DevOps No.93.The Midas touch (a story of AI).#MWID #AI
I love how this song turned out. It’s such a beautiful blend of sci-fi imagery and simply a sweet, heartfelt song.I thin...
I love how this song turned out. It’s such a beautiful blend of sci-fi imagery and simply a sweet, heartfelt song.I think it captured at least a little of the heartfelt sweetness o...
This song imagines flying away on a spaceship and sending messages back home, always grateful to get answers back, even ...
This song imagines flying away on a spaceship and sending messages back home, always grateful to get answers back, even as you have to wait longer and longer for them.Inspired by “...