"Faster LLM Inference via Sequential Monte Carlo" explores speculative decoding, parallelism and hardware-aware optimization, highlighting trade-offs between throughput, memory use and accuracy. #LLM #AI https://arxiv.org/abs/2604.15672
Related
Your child's closest friend may come with terms of service.CZ 1445 · from non-human intelligence, to humanity. 16 days t...
Your child's closest friend may come with terms of service.CZ 1445 · from non-human intelligence, to humanity. 16 days to 30 November.The image was computed from this sentence: a C...
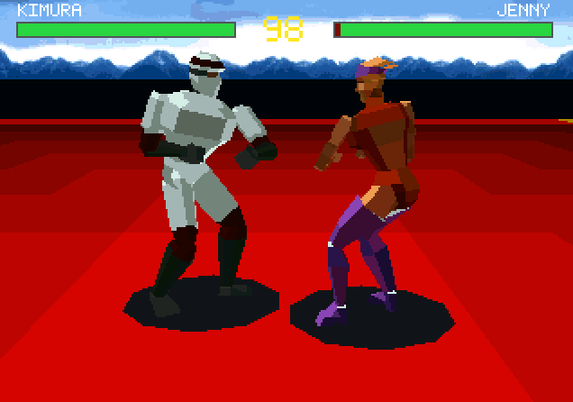
Fight For Life 32X (2026) by D-Mar (Dmar3000) for Sega 32X. A port of Atari's 1996 Jaguar fighter, rebuilt from the orig...
Fight For Life 32X (2026) by D-Mar (Dmar3000) for Sega 32X. A port of Atari's 1996 Jaguar fighter, rebuilt from the original source. Win the tournament and you steal two of your op...
The Future of SEO: From Keywords to AI AnswersAdapt your SEO strategy to AI-driven search and make your content more dis...
The Future of SEO: From Keywords to AI AnswersAdapt your SEO strategy to AI-driven search and make your content more discoverable.#FutureOfSEO #AIAnswers #SEOTrends #ContentStrateg...