📊 DeepSeek V3.2 Exp (Non-reasoning) — the actual numbers GPQA: 73.8% MMLU-Pro: 83.6% Humanity's Last Exam: 9% Long Context Reasoning: 44.7%💰 44.1 intelligence points per dollarMeasured independently, not self-reported →https://olud.ai/leaderboard.html#LLM #Benchmarks #OpenSource #AI
Related
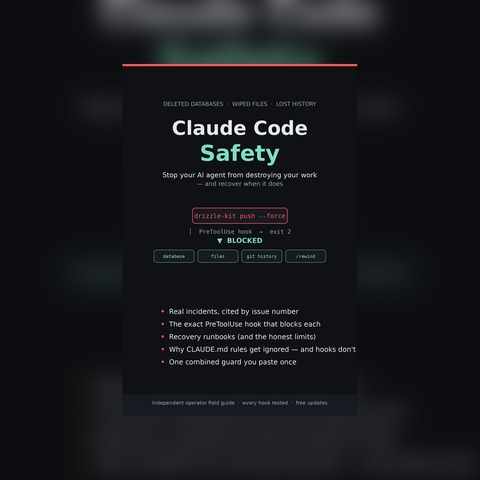
Claude Code Safety: Stop Your AI Agent from Destroying Your Work by yurukusa is free with a Leanpub Reader membership! O...
Claude Code Safety: Stop Your AI Agent from Destroying Your Work by yurukusa is free with a Leanpub Reader membership! Or you can buy it for $5.99! https://leanpub.com/claude-code-...
@eff Yikes on Bikes."Our consortium unites industry leaders, including an AI-enabled utilization management andcare mana...
@eff Yikes on Bikes."Our consortium unites industry leaders, including an AI-enabled utilization management andcare management platform (Zyter), a secure federal-grade software inf...
⚡ Remote Research Engineer, Post-Training at Deepgram.✅ Apply here: https://jobicy.com/jobs/161406-research-engineer-pos...
⚡ Remote Research Engineer, Post-Training at Deepgram.✅ Apply here: https://jobicy.com/jobs/161406-research-engineer-post-training#RemoteJobs #DataJobs #MachineLearning #BusinessIn...