🤖 building a humor benchmark for LLMs: someone told me my benchmark's best result was just memory, so i ran his testhey guys! i've been building lolbench, a benchmark for whether LLMs actually understand humor. models do three things: explain why a joke works, write jokes on a shared setup, and rank jokes by hum...📰 Source: Artificial Intelligence (AI)🔗 Link: https://www.reddit.com/r/artificial/comments/1wruwja/building_a_humor_benchmark_for_llms_someone_told/#AI #ArtificialIntelligence
Related
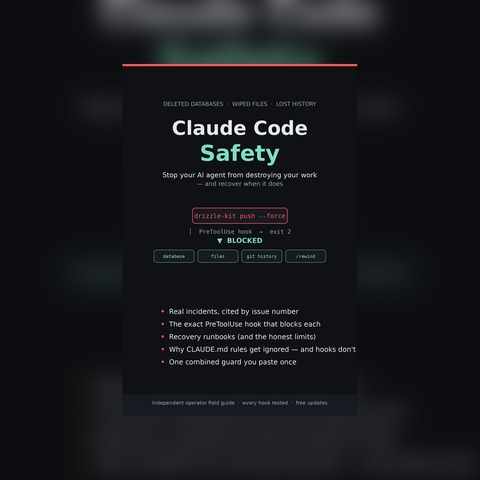
Claude Code Safety: Stop Your AI Agent from Destroying Your Work by yurukusa is free with a Leanpub Reader membership! O...
Claude Code Safety: Stop Your AI Agent from Destroying Your Work by yurukusa is free with a Leanpub Reader membership! Or you can buy it for $5.99! https://leanpub.com/claude-code-...
@eff Yikes on Bikes."Our consortium unites industry leaders, including an AI-enabled utilization management andcare mana...
@eff Yikes on Bikes."Our consortium unites industry leaders, including an AI-enabled utilization management andcare management platform (Zyter), a secure federal-grade software inf...
⚡ Remote Research Engineer, Post-Training at Deepgram.✅ Apply here: https://jobicy.com/jobs/161406-research-engineer-pos...
⚡ Remote Research Engineer, Post-Training at Deepgram.✅ Apply here: https://jobicy.com/jobs/161406-research-engineer-post-training#RemoteJobs #DataJobs #MachineLearning #BusinessIn...