Ever wonder what actually happens inside an LLM? KV Cache, Flash Attention, Speculative Decoding, LoRA — LLM Internals by breaks it all down with numeric examples, not hand-waving. Full resource breakdown in the next post. #MachineLearning
Related
i prossimi due incontri alla biblioteca pagliarani: g. garrapa 12 nov., e. davoglio 13 nov. Gli incontri programmati dal...
i prossimi due incontri alla biblioteca pagliarani: g. garrapa 12 nov., e. davoglio 13 nov. Gli incontri programmati dalla Biblioteca Elio Pagliarani nel mese di novembre 2026:inco...
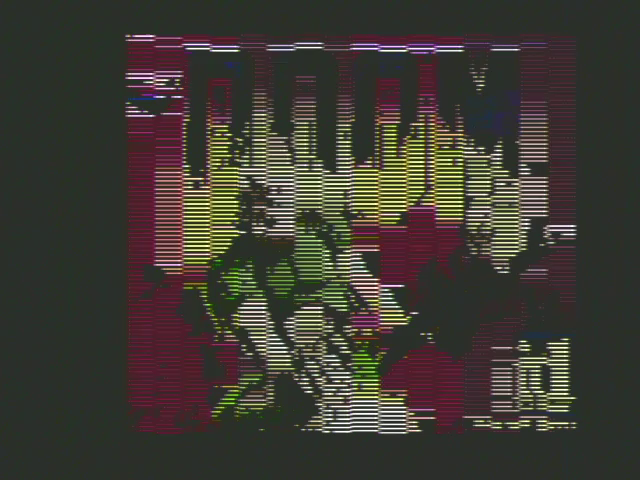
Doom for #Atari2600 console with UnoCart or PlusCart https://forums.atariage.com/topic/394341-doom-port-for-atari-2600-f...
Doom for #Atari2600 console with UnoCart or PlusCart https://forums.atariage.com/topic/394341-doom-port-for-atari-2600-for-pluscartunocart-ai-assisted/ #AI #atari #doom
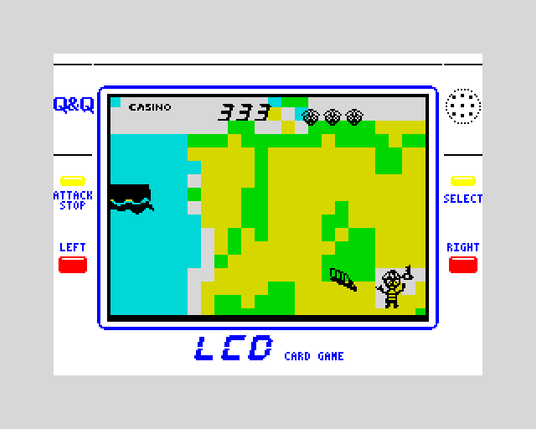
Treasure Island (2026) by FlunkyRetro for ZX Spectrum. An LCD handheld reborn: carry the key to the hut, then the chest ...
Treasure Island (2026) by FlunkyRetro for ZX Spectrum. An LCD handheld reborn: carry the key to the hut, then the chest to the ship, while a bird tries to steal it. At 500 points y...