TL;DR: vLLM 0.30.0 can keep a model's weights in a long-running daemon so that engines restart...#llm #vllm #selfhosted #debugging #software #coding #development #engineering #inclusive #communityvLLM's weight cache can serve another checkpoint's weights when the tensor layout matches
Related
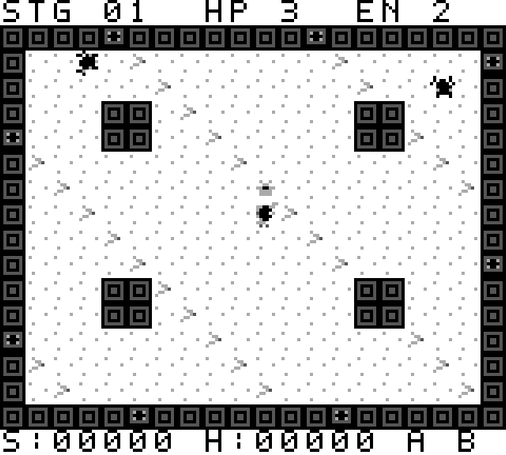
Trapkeeper (2026) by devgb for Game Boy. Dig pits with your shovel, lure monsters in and bury them before they climb out...
Trapkeeper (2026) by devgb for Game Boy. Dig pits with your shovel, lure monsters in and bury them before they climb out, across 20 levels in five themed worlds. ⛏️🎁 https://devgb....
AI経由売上の半数が検索流入扱いに。 効果測定 の課題とデータ開示への期待https://digiday.jp/agencies/media-briefing-the-iab-finds-ai-measurement-standards-e...
AI経由売上の半数が検索流入扱いに。 効果測定 の課題とデータ開示への期待https://digiday.jp/agencies/media-briefing-the-iab-finds-ai-measurement-standards-elusive-for-publishers-amid-platform-data-gaps/#digiday #Agen...
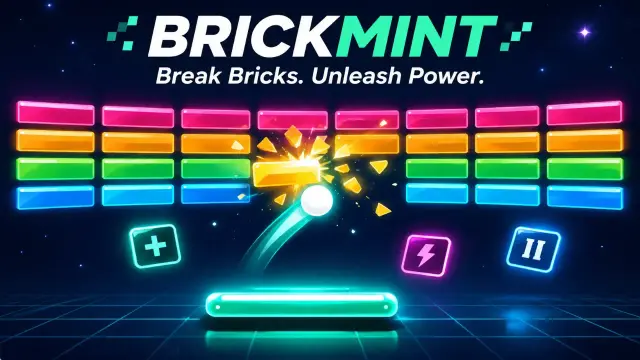
🎮 Can AI understand a game without seeing its source code?We gave ChatGPT a compiled Windows brick-breaker game and expl...
🎮 Can AI understand a game without seeing its source code?We gave ChatGPT a compiled Windows brick-breaker game and explored its mechanics through disassembly: ball physics, collis...