New post: Laya vs Jev, ten days later 🧠⚖️Ten days ago I benchmarked two "System One" decision models for my LLM router: Jev (TypeSafe, hosted) was usable as-is, Laya (open weights) zero-shot was not. Laya's README says "fine-tune me", so I did, on a 16 GB M4 MacBook.🔁 Laya 0.3.6 → 0.3.24: 18 releases, but the weights are byte-identical. Same numbers.🆕 New open rivals on my 80-prompt bench:• Laya typed-decisions: 71% topic, but never confident → over-provisions everything• Von 1.3: closest to gold out of the box (48%), but over-confident• Kev-0.8B: 81% topic, 100% multilingual, very under-confidentJev 1.13: 89% topic, 72.5% same route as gold, still the only one usable as-is.🎯 Fine-tuning Laya on my own labels (not Jev's: distilling Jev is against TypeSafe's terms):• 480 labelled prompts → 1,920 training items• official Apple Silicon script, MPS• 41.5 min for 4 epochs, 15.4 GB peak memory• rule of thumb: ~6 s per labelled promptResults:• topic 59% → 85%• complexity 45% → 72.5% (= Jev)• ...
Related
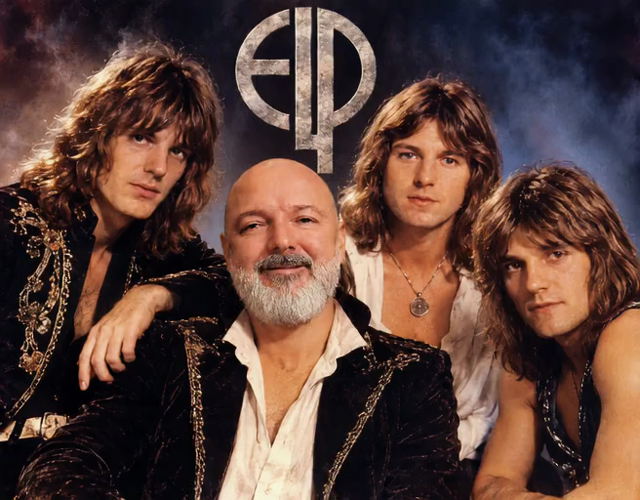
🧶 6/6 #rockforcoffee V průběhu dalších desetiletí se kapela několikrát znovu spojila. Její příběh však poznamenala smrt ...
🧶 6/6 #rockforcoffee V průběhu dalších desetiletí se kapela několikrát znovu spojila. Její příběh však poznamenala smrt Keitha Emersona🩶 v roce 2016 a Grega Lakea🩶 v témže roce. Ca...
Anthropic's major backers—Google (14%), Amazon (15%), Microsoft, Nvidia, and AMD—bought $26 billion in non-voting shares...
Anthropic's major backers—Google (14%), Amazon (15%), Microsoft, Nvidia, and AMD—bought $26 billion in non-voting shares alongside the IPO. The arrangement highlights how deeply en...
Build vs Buy AI Solutions: Which Is Right for Your Business?Should you build a custom AI solution or buy an existing pla...
Build vs Buy AI Solutions: Which Is Right for Your Business?Should you build a custom AI solution or buy an existing platform? Explore the differences in cost, scalability, flexibi...