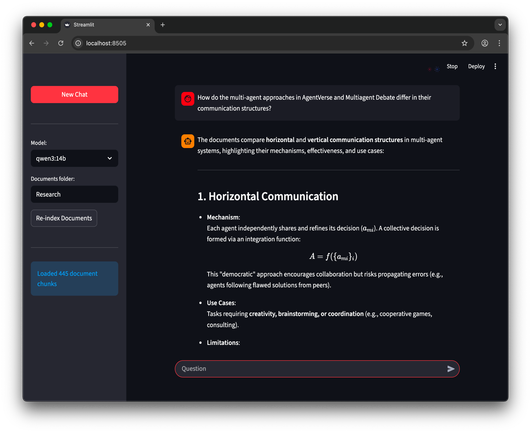
local-LLM-with-RAGThis project is an experimental sandbox for testing out ideas related to running local Large Language Models (LLMs) with Ollama and Pydantic AI to perform agentic Retrieval-Augmented Generation (RAG) for answering questions based on your documents. The agent can decide when and how to search documents, unlike fixed RAG pipelines. We use Ollama to create embeddings with nomic-embed-text stored in LanceDB for vector search.**Technologies Used**:- Pydantic AI: Type-safe agent framework with tool calling- Ollama: Platform for running Large Language Models locally- LanceDB: Vector database for storing and retrieving embeddings- MarkItDown: Microsoft's document converter for PDF, Office files, and more- Streamlit: Web framework for interactive applications- UV: Fast Python package installer and resolverhttps://github.com/amscotti/local-LLM-with-RAG#ai #LLM #RAG
local-LLM-with-RAGThis project is an experimental sandbox for testing out ideas related to running local Large Language ...