A practical cost model for self-hosted LLM serving: how continuous batching, token mix, and GPU utilization decide your real price per million tokens.#llm #vllm #performance #devops #software #coding #development #engineering #inclusive #communityWhat Does It Actually Cost to Self-Host an LLM? The Batching Math Nobody Shows You
Related
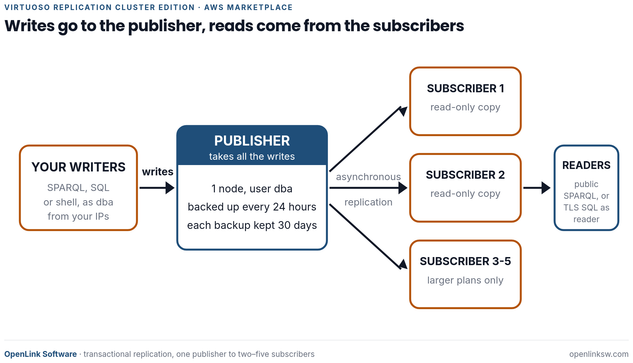
When your data, information, and knowledge must stay available, replication matters.Virtuoso Replication Cluster Edition...
When your data, information, and knowledge must stay available, replication matters.Virtuoso Replication Cluster Edition gives you transactional replication with one publisher serv...
DeepSeek has opened the main features of its app as APIs, letting developers rebuild web search, file parsing, OCR, spee...
DeepSeek has opened the main features of its app as APIs, letting developers rebuild web search, file parsing, OCR, speech recognition and synthesis in their own products. The deep...
Egyptian potato exporter deploys ORTH AI across 54,000 acres.DALTEX announced the deployment of ORTH’s artificial - inte...
Egyptian potato exporter deploys ORTH AI across 54,000 acres.DALTEX announced the deployment of ORTH’s artificial - intelligence platform across its Egyptian potato - farming opera...