Have you ever found yourself stuck in this question: "will this model fit on my GPU?". A lot of us have. The honest answer is always "it depends on quantization and context length," which is true but not actually useful when someone just wants to know if their card can run the model they want to try.So here is the practical version. A real, tier-by-tier breakdown of what actually fits on the VRAM sizes people are most commonly working with, based on typical 4-bit quantization with reasonable context headroom.Why does the same model need different amounts of VRAM on different GPUs?Because model size is not the only variable. Two things change the actual footprint dramatically.Quantization level: since dropping from full precision to 4-bit roughly quarters the memory a model's weights needContext length: since every additional token of context adds to the KV cache sitting on top of the base weightsThis guide assumes standard 4-bit quantization, commonly written as Q4 or Q4_K_M, with mode...
Related
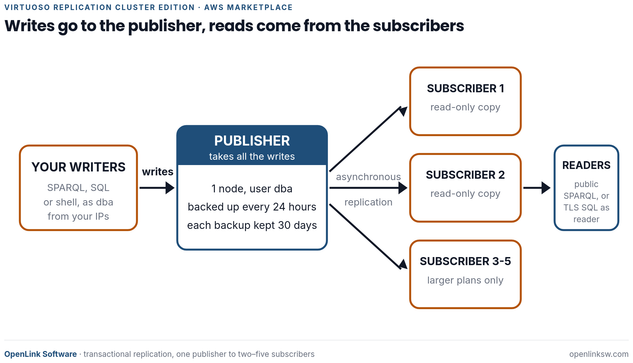
When your data, information, and knowledge must stay available, replication matters.Virtuoso Replication Cluster Edition...
When your data, information, and knowledge must stay available, replication matters.Virtuoso Replication Cluster Edition gives you transactional replication with one publisher serv...
DeepSeek has opened the main features of its app as APIs, letting developers rebuild web search, file parsing, OCR, spee...
DeepSeek has opened the main features of its app as APIs, letting developers rebuild web search, file parsing, OCR, speech recognition and synthesis in their own products. The deep...
Egyptian potato exporter deploys ORTH AI across 54,000 acres.DALTEX announced the deployment of ORTH’s artificial - inte...
Egyptian potato exporter deploys ORTH AI across 54,000 acres.DALTEX announced the deployment of ORTH’s artificial - intelligence platform across its Egyptian potato - farming opera...