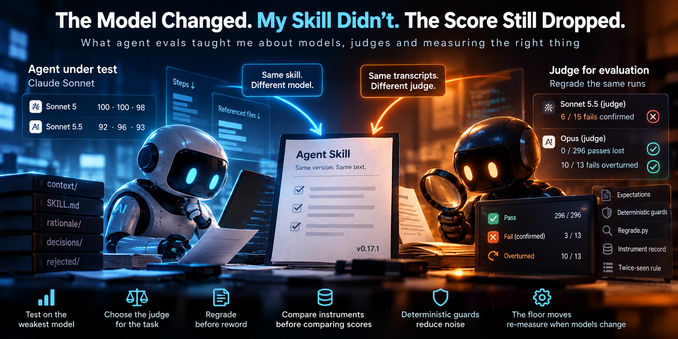
My agent eval suddenly got much worse. The skill had barely changed, but the model behind the alias had.That led to a more uncomfortable discovery: sometimes the LLM judge was noisier than the agent being tested.On one regrade of 15 stored failures, the same judge confirmed only 6 of its own verdicts.The lesson wasn't "use a stronger model everywhere". It was:Test the agent on the weakest model you intend to support. Measure which model is actually reliable enough to judge it. And record the whole instrument, not just the score.New article:https://blog.technopathy.club/the-model-changed-my-skill-didn-t-the-score-still-dropped#AI #LLM #Evals #CodingAgents #OpenSource
My agent eval suddenly got much worse. The skill had barely changed, but the model behind the alias had.That led to a mo...