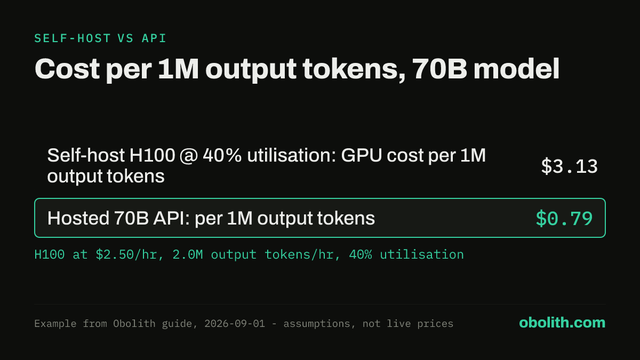
40% utilisation: $3.13 GPU cost self-hosted vs $0.79 via API, per 1M output tokens (70B model).Guide example: H100 at $2.50/hr, 2.0M output tokens/hr.GPU hourly rates hide the cost of idle time.#GPU #LLM #MLOps
40% utilisation: $3.13 GPU cost self-hosted vs $0.79 via API, per 1M output tokens (70B model).Guide example: H100 at $2...