In our 50-fault benchmark, Claude Code with a shell launched its own pods on 13 faults. On one, it dropped two MongoDB collections and still submitted the wrong diagnosis. The benchmark's prompt said a fix stage would follow, allowed resource changes, and told it not to ask for confirmation.The other arm had read-only tools only, and averaged 64 s to a diagnosis against 191 s.https://radarhq.io/blog/ai-sre-give-your-agent-context-first?utm_source=mastodon&utm_campaign=ai-sre-give-your-agent-context-first-launch-2026-10&utm_content=masto#Kubernetes #SRE #DevOps #AI
Related
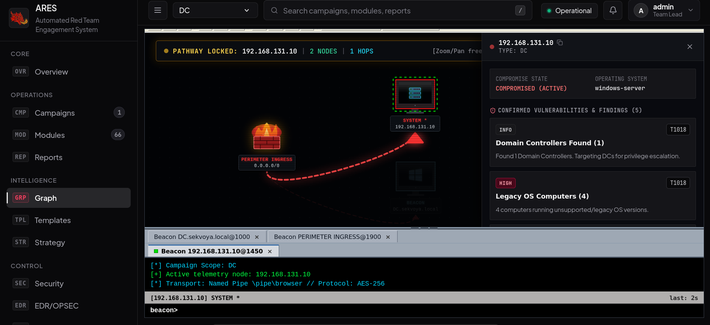
AI in Cybersecurity, Part 32: Automating Active Directory Pentests with ARESARES - an open-core autonomous red-team plat...
AI in Cybersecurity, Part 32: Automating Active Directory Pentests with ARESARES - an open-core autonomous red-team platform that orchestrates 66+ attack modules, maps enterprise t...
Wake me up when AI can...https://stoppels.ch/2026/10/03/wake-me-up-when-ai-can.html#ai
Wake me up when AI can...https://stoppels.ch/2026/10/03/wake-me-up-when-ai-can.html#ai
https://omdaruliterature.blogspot.com/2026/11/cassiopeia-wiki-selected-where-to-start.html Cassiopeia - Wiki - Selected ...
https://omdaruliterature.blogspot.com/2026/11/cassiopeia-wiki-selected-where-to-start.html Cassiopeia - Wiki - Selected - Where to Start - AInquiries #AI #Essays in #English on #sp...