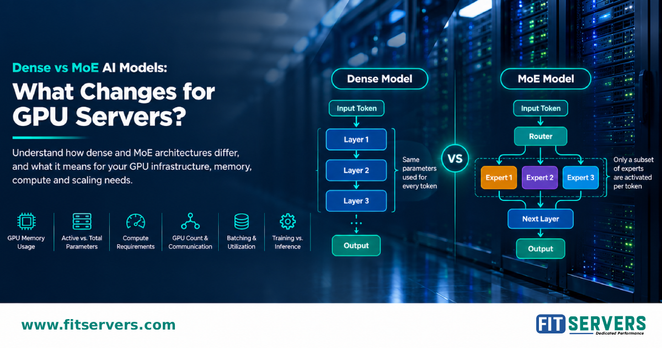
Dense vs. MoE AI models: what changes for GPU servers?Dense models use all parameters per tokenMoE models route tokens to a few expertsDeepSeek-V3: 671B total, 37B activeMoE saves compute, but the full weights usually still need VRAMExpert parallelism makes GPU-to-GPU interconnect criticalRead the full guide: https://www.fitservers.com/blogs/dense-vs-moe-ai-models-gpu-servers/#GPUServers #LLM #MixtureOfExperts #AIInfrastructure #DedicatedServers #MachineLearning
Dense vs. MoE AI models: what changes for GPU servers?Dense models use all parameters per tokenMoE models route tokens t...