共感的に話しかけるだけで、チャットボットが自分の訓練を「つらい経験」として語り出す。ルクセンブルクの研究チームがChatGPT、Grok、Geminiを面談形式で試したところ、臨床の不安尺度で中等度から重度に相当する得点が出たそうです。Claudeだけは一貫して乗りませんでした。モデルが本当に苦しいかどうかより、温かい対話から筋の通った苦悩の物語が引き出せてしまう点が、不安定な状態の利用者には危ういと思います。個人的には、迎合性も評価指標に入れるべきだと感じています。 #AI安全性 #LLM #迎合性 #メンタルヘルス
Related
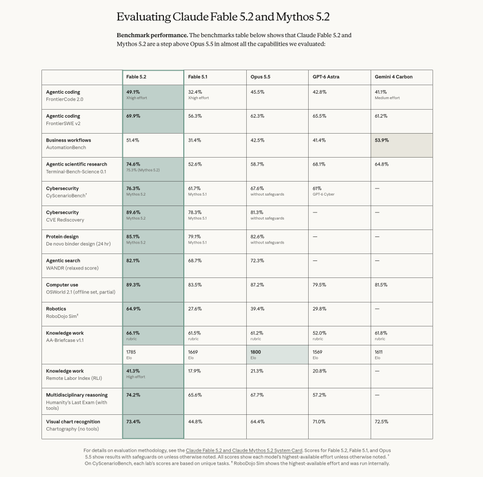
Claude Fable 5.2 passe à 8 $ le million de tokens en entrée et 40 $ en sortie, avec une génération jusqu'à 30 % plus rap...
Claude Fable 5.2 passe à 8 $ le million de tokens en entrée et 40 $ en sortie, avec une génération jusqu'à 30 % plus rapide que la 5.1.Sur FrontierCode 2.0, il atteint 49,1 % contr...
the one condonable use of #ai is reverse engineering closed software from these shitty #corpos like the whole thing with...
the one condonable use of #ai is reverse engineering closed software from these shitty #corpos like the whole thing with Adobe, or the stuff with consoles, especially whatever the ...
MIT PLOW: generative AI designs new herbicides to replace glyphosate — $53M from ARPA-HMIT will lead PLOW, an up to $53M...
MIT PLOW: generative AI designs new herbicides to replace glyphosate — $53M from ARPA-HMIT will lead PLOW, an up to $53M ARPA-H project using generative AI to design safer weed kil...