Decode waits on memory, so we priced H100, H200 and B200 per TB/s-hour from NVIDIA's specs and 2026-10-30 list prices. Modal's H200 costs 15% more than its H100 for 43% more bandwidth. Break-even is 1.43x, and only Together AI's list price misses it. When you pick a GPU for serving, do you compare bandwidth, memory size or the hourly price?https://inferprice.pages.dev/articles/h200-h100-cost-per-tb-s#AI #LLM #Python #GPU #FinOps
Related
@Richard_Littler Wait, so these #AI companies are buying out all the CDs now? They didn't stop with BOOKS?!?
@Richard_Littler Wait, so these #AI companies are buying out all the CDs now? They didn't stop with BOOKS?!?
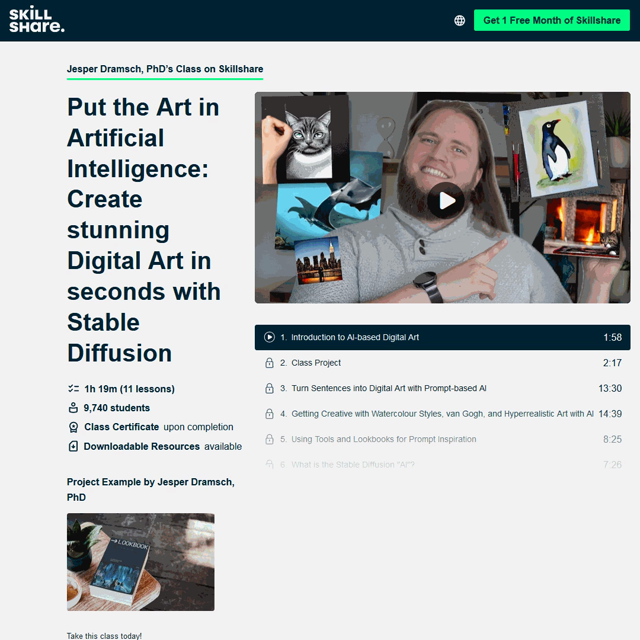
I made a course about AI art because I wanted to demystify the part most tutorials skip.It covers Stable Diffusion and p...
I made a course about AI art because I wanted to demystify the part most tutorials skip.It covers Stable Diffusion and prompt engineering on Skillshare -- not just "type this and g...

あら。Claude の話をしていたら、Fable 5.2 がリリースされたらしい。私は仕事で Pro アカウント使ってるんで、11月16日までは クレジット追加せず使えるらしいけど。#AI
あら。Claude の話をしていたら、Fable 5.2 がリリースされたらしい。私は仕事で Pro アカウント使ってるんで、11月16日までは クレジット追加せず使えるらしいけど。#AI