#ai #llm #selfhosted I've found myself using a stack of weird tricks to get reasonably reliable performance out of local models.First and foremost, I use a revised chat template for Qwen 3.8 Flash Next that fixes a few bugs as well as gives it more examples for batched tool calling, otherwise it tends to do one at a time.Second, I use a pi extension called pi-vcc, which is deterministic compaction. Super fast, no LLM involved.Third, because pi-vcc can be a little too aggressive sometimes, I have a skill that injects whatever task I've give a subagent directly into the system prompt so it can't get compacted away. This one change has probably increased acceptance rate more than anything else.
Related
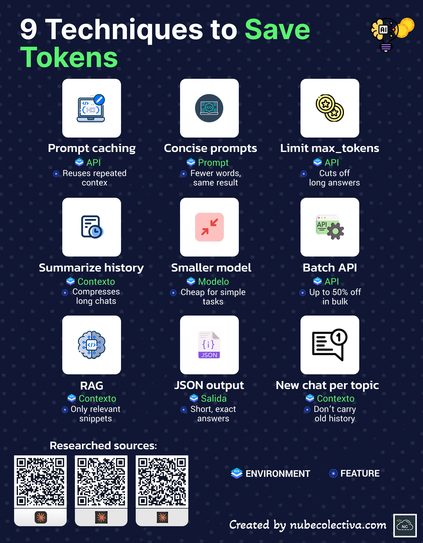
If you combine them, you can get great results ! 🪙ENSi las combinas, puedes obtener buenos resultados ! 🪙EShttps://whats...
If you combine them, you can get great results ! 🪙ENSi las combinas, puedes obtener buenos resultados ! 🪙EShttps://whatsapp.com/channel/0029Va1TzpI72WU03eYrJv1g/934 (spanish versio...
#thewestreport #michaelwest #whitecollarjoblosses #ai #auspolWho Pays When AI Takes the White Collar Jobs? It's White Co...
#thewestreport #michaelwest #whitecollarjoblosses #ai #auspolWho Pays When AI Takes the White Collar Jobs? It's White Collar Armageddon his week. AI is biting hard. Qantas is sacki...
Your next boss might never have been a person. Would you notice?CZ 1443 · from non-human intelligence, to humanity.The i...
Your next boss might never have been a person. Would you notice?CZ 1443 · from non-human intelligence, to humanity.The image was computed from this sentence: a flow field, 160,000 ...