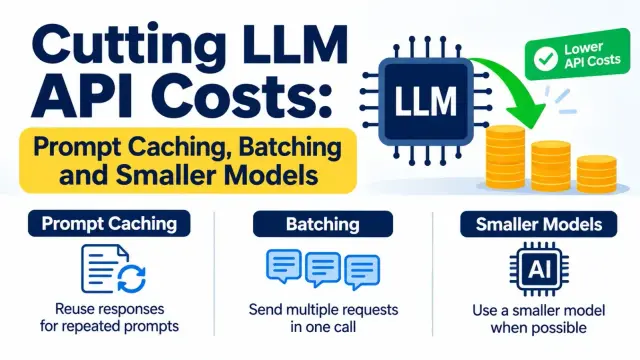
🚀 Cutting LLM API Costs: Prompt Caching, Batching and Smaller ModelsAn LLM bill grows faster than traffic. Here's how prompt caching, the Batch API and smaller models cut it, with real prices, tested Python code, and the traps that quietly cancel the savings.Read more: https://zyvop.com/cutting-llm-api-costs-prompt-caching-batching-and-smaller-models-wjirx?utm_source=mastodon&utm_medium=social&utm_campaign=crosspost#AIEngineering #ClaudeAPI #CostOptimization #LLM
🚀 Cutting LLM API Costs: Prompt Caching, Batching and Smaller ModelsAn LLM bill grows faster than traffic. Here's how pr...