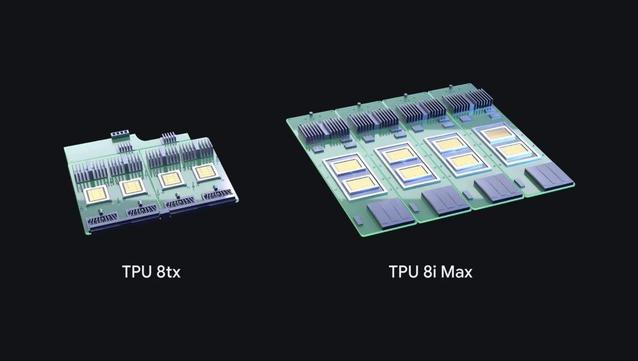
Google split its eighth-generation Tensor Processing Unit between training and inference at Google Cloud Next. TPU 8t superpods scale to 9,600 chips, 2 PB of shared high-bandwidth memory, and 121 ExaFlops. TPU 8i holds a model's active working set in 384 MB of on-chip SRAM alongside 288 GB of HBM, targeting 80 percent better performance-per-dollar. Both arrive later this year. #AI #Technology
Google split its eighth-generation Tensor Processing Unit between training and inference at Google Cloud Next. TPU 8t su...