
Qwen3 4B vs 0.6B on a 6 GB GPU: Speed, Memory, and Answer Quality
For my personal retrieval-augmented generation (RAG) study, I needed a local model to answer...
5336 articles tagged with AI Hardware
For my personal retrieval-augmented generation (RAG) study, I needed a local model to answer...

Merck opened a molybdenum precursor plant in Eumseong, Korea, targeting 3D NAND wiring first and later DRAM and logic chips.

Interactive video "world models" are having a moment — Matrix-Game, HY-World, and others generate...
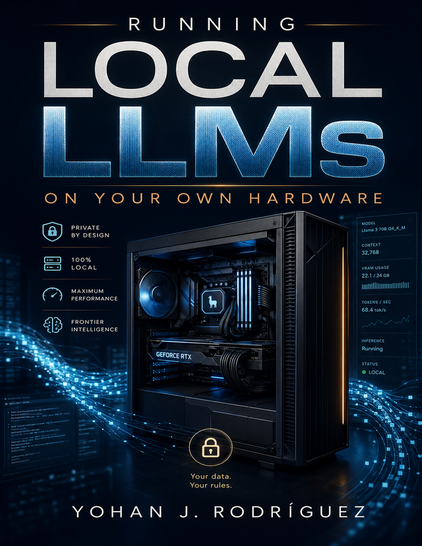
Running Local LLMs on Your Own Hardware: A Practical Guide to Private, Offline, and Self-Hosted Large Language Models by Yohan J. Rodríguez 📖 on Leanpub!A hands-on guide to downloa...
Recursive has released Flint, a free open-weights coding model designed to run locally on consumer hardware, enabling offline use and code privacy.Built largely using the company's...
HONG KONG, Oct. 21, 2026 (GLOBE NEWSWIRE) -- 3 E Network Technology Group Limited (Nasdaq: MASK) (the 'Company” or '3 E Network”), a business-to-business ('B2B”) information techno...

WASHINGTON — New York Gov. Kathy Hochul’s plan to open a computer chip plant outside Utica is raising concerns among federal officials who fear that China could gain greater access...
OnePlus may call dibs on a new Snapdragon ‘Pro’ chip, and you’re allowed to feel jealousA new OnePlus phone could soon arrive with an upcoming Snapdragon 8 Gen Pro chip and some sp...
why did AI take off now and not in 1999? the ideas mattered, but the hardware is the real story.wrote up how it actually works, from tokens, embeddings and self-attention to GPUs, ...
Tens of thousands of #Nvidia #GPU sit idle in #Meta's #Prometheus supercluster, just waiting for a failureIn an eight-GPU node, the chance of having a GPU fail is relatively low. I...

Sam Altman joins me to break down AI consciousness, recursive self-improvement, and how AI could help discover new ...

Meta is building Prometheus, a massive AI supercomputer designed to scale to around **1 million GPUs**. But why does AI need ...

I wanted to dictate on my PC without paying for a subscription. So I built Wisperno: hold a hotkey,...
#HPE says it will run the first #supercomputer benchmarks on the #Moon — GPU-powered #SpaceborneComputer4 is slated to ride a rover to lunar south pole to test #AI and #HPC benchma...

Edge medical segmentation must reconcile small model size, high accuracy, and fast inference. TernScope addresses this tradeoff through model--hardware co-design, learning a compac...

AI infrastructure on Kubernetes: NVIDIA GPU Operator automation, MIG slicing, Kubelet Topology Manager NUMA alignment, Dynamic Resource Allocation, and KEDA scaling.
TornadoVM version 7 brings #GPU workloads directly from #Java - https://www.infoq.com/news/2026/10/tornadovm-7-gpu/ #llm
Huawei plans Q1 2027 launch of new AI chip as it takes on NvidiaHuawei is accelerating the launch of its next-generation Ascend 960DT AI chip as it pushes to compete with Nvidia an...

Your daily AI news update for October 21, 2026, in under 3 minutes! Today's stories: ⚡ Google open-sources TorchTPU to ...
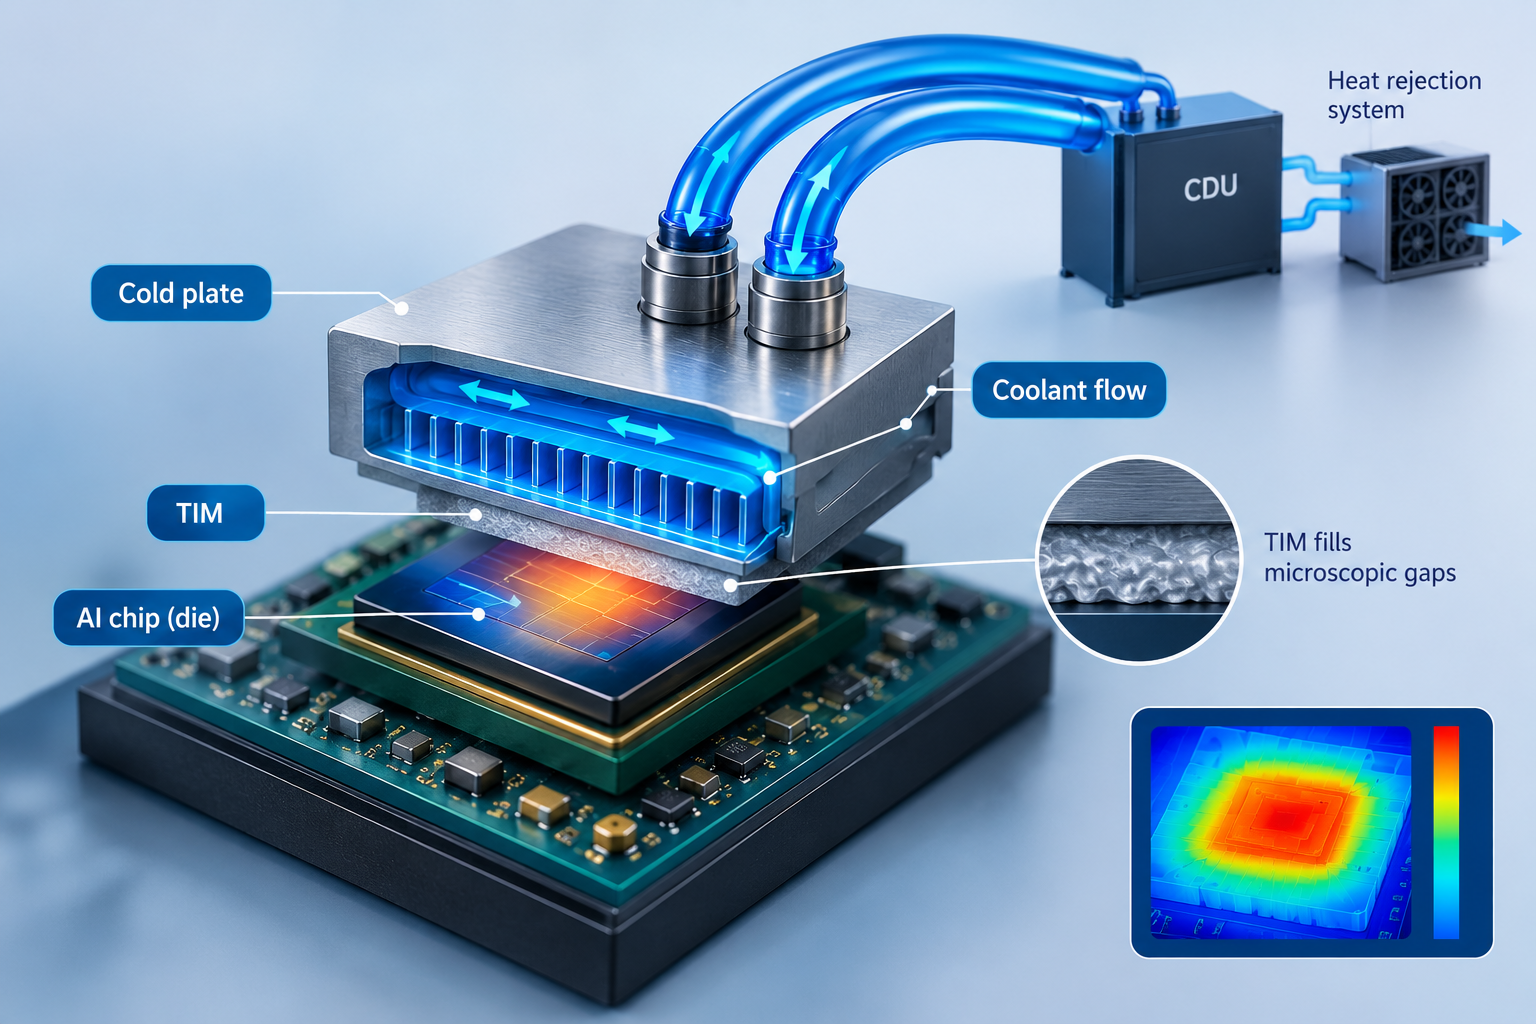
Thermal interface materials, cold plate design, coolant flow, and simulations help engineers manage heat and reliability in AI chips. Thermal interface material (TIM) remains a key...
複数については、タムズでもしっかり話し合っておかないとオラにGPUを分けてくれ! 暇そうなMacを使ってAI開発を分散処理 https://www.gizmodo.jp/article/2610-distributed-ai-development-mac-minions/#Apple #LLM #news #bot
Where does all the hardware go? The hidden environmental footprint of AI data centres https://theconversation.com/where-does-all-the-hardware-go-the-hidden-environmental-footprint-...

Your 60-second AI news briefing for 21 October 2026: the 5 biggest artificial intelligence stories today, fact-checked. 1️⃣ China's ...
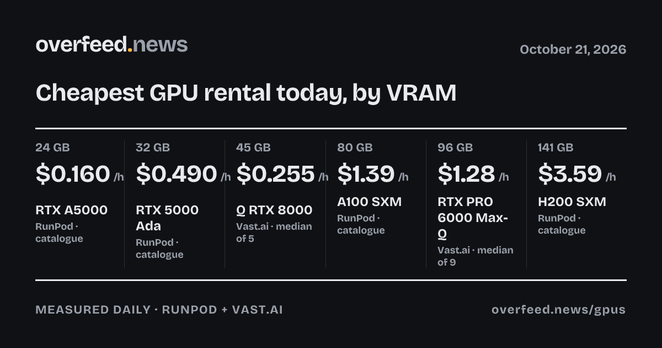
Cheapest GPU rentals today (2026-10-21), by VRAM:24GB RTX A5000 $0.160/h (RunPod)45GB Q RTX 8000 $0.255/h (Vast.ai)48GB RTX A6000 $0.330/h (RunPod)80GB A800 PCIE $0.468/h (Vast.ai)...