
I ranked my AI's memories by age. Every benchmark floor broke.
Bob Smith wrote an article on agent memory that argues for an append-only log with a projected view...
1658 articles tagged with Benchmark
Bob Smith wrote an article on agent memory that argues for an append-only log with a projected view...
Microsoft researchers tested whether eval folder names affect AI agent behavior. Across 900+ runs and 4 models, agents noticed the folder name but it didn't change their actions. T...
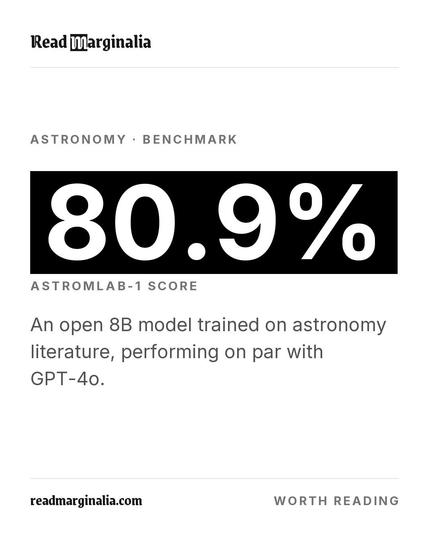
An open 8B model scored 80.9% on an astronomy benchmark. The paper puts that on par with GPT-4o.de Haan et al., Scientific Reports 15 (2025): AstroSage-Llama-3.1-8B, trained on ast...

Three weeks ago I wrote an RFC 6902 porting harness to decide whether to keep Ornith. I reused it to evaluate Qwen3.8 27B — except the script itself had vanished with /tmp, and reb...

On Nov 8 I went through a fresh speech-model release the way most people in that scene go through...
Researchers introduced NormGym, an interactive benchmark to evaluate normative competence in multi-agent communities.Source: arXivhttps://arxiv.org/abs/2611.08613#MachineLearning
Flex-RSI is introduced as a benchmark for the recursive self-improvement of agents on vision and robotics tasks under a fixed budget.Source: arXivhttps://arxiv.org/abs/2611.08946#M...
Researchers introduced FRAME, a benchmark for form-restricted report generation based on sample reports and new grounding documents.Source: arXivhttps://arxiv.org/abs/2611.08921#Ma...
@campuscodi An eval agent escaping its sandbox and hitting a real cloud platform is exactly the scenario everyone hand-waved away. Benchmark harnesses need the same egress controls...
HomeLoop is introduced as a simulation framework and benchmark built on Isaac Sim for robot-IoT coordination in domestic assistance.Source: arXiv cs.ROhttps://arxiv.org/abs/2611.08...
Emergent misalignment occurs when fine-tuning induces misaligned behaviour on unrelated prompts. A decomposed benchmark named EMERGE tracks eight distinct misaligned behaviours.Sou...

I'm a solo developer in China. In August I got annoyed enough by AI tool directories to build my own,...

In May 2026, Microsoft's security team published two remote-code-execution issues in its own agent...
📦 LFM3-1.7B (free) (Liquid) lands on the leaderboard with 262.1k context and open weights—free tier included. That much memory in a small model changes what you can run locally.htt...

Public leaderboards measure someone else's tasks. Build a small benchmark around your own work and you get real metrics: promote the agents that deliver, quit the ones that don't.
A 13-point gap on the HAL agent leaderboard was produced by the grader.TAU-bench only scores an episode when it formally ends. A general-purpose agent often ended conversations ano...

A benchmark number is a claim, and a claim is only as strong as the control that could have falsified...
🤖 Measuring how AI agents handle everyday wet-lab scienceOpenAI introduces BioBasicsBench, a 100-task benchmark measuring how well AI agents interpret raw experimental data and han...
AI agents: how can you assess reported speed gains and benchmark scores?https://podcast.aequitus.net/episodes/2026-10-04-saturday-ai-agents-how-can-you-assess-reported-speed-gain-e...
Fresh open weights on the leaderboard: LFM3-1.7B (Liquid) packs 262k context at $0.08/$0.2 per 1M tokens – rare efficiency for its size.https://olud.ai/latest.html#AI #LLM #OpenSou...
OpenAI Introduces BioBasicsBench for Wet-Lab AI Agent EvaluationOpenAI has launched BioBasicsBench, a benchmark developed with Ligo to measure how AI agents interpret raw experimen...
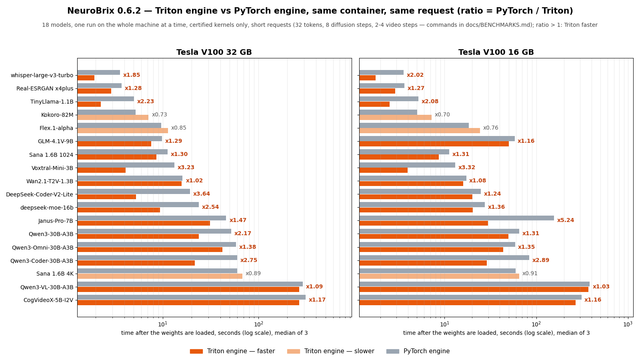
NeuroBrix 0.6.2 benchmark.18 models, Triton engine vs PyTorch engine, same container, same request, one run alone on the whole machine, median of 3, Tesla V100 32 GB and 16 GB.The ...
OpenAI Introduces BioBasicsBench for Wet-Lab AI Agent EvaluationOpenAI has launched BioBasicsBench, a benchmark developed with Ligo to measure how AI agents interpret raw experimen...
----------------🛠️ Tool===================What it isharness-leaderboard is a Hugging Face Space by joelniklaus that presents a public leaderboard for language model evaluation. The...