/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1676 articles tagged with Benchmark

Latest Trending
Mastodon discussion Sep 24

📦 Fresh on the leaderboard: Aion 3.5 Mini (AionLabs)Context: 262.1k tokens · $0.7 in / $1.4 out per 1M · commercialAll t...

📦 Fresh on the leaderboard: Aion 3.5 Mini (AionLabs)Context: 262.1k tokens · $0.7 in / $1.4 out per 1M · commercialAll the latest models, tracked hourly:https://olud.ai/latest.html...

Benchmark
9
Dev.to tutorial Sep 24

Designing an L3 Enterprise AI Benchmark Task for Cross-Functional Payment Incident Triage

AI agents often look impressive when they answer a clean question using one tidy data source....

Benchmark
12
Dev.to tutorial Sep 24

Your Model Isn't Bad. Your Eval Set Might Be Circular.

I built a rule-based sugar detector and a fine-tuned model to compete against it, ran them against...

Benchmark
12
Mastodon discussion Sep 24

You've been there. You run the eval, the number comes back, and something about it doesn't sit...#ai #evaluation #llm #p...

You've been there. You run the eval, the number comes back, and something about it doesn't sit...#ai #evaluation #llm #programming #software #coding #development #engineering #incl...

LLM Benchmark
27
Dev.to tutorial Sep 24

7 Agent Eval Mistakes That Cost Me Weeks (And the One-Line Fixes That Ended Them)

You've been there. You run the eval, the number comes back, and something about it doesn't sit...

Benchmark
44
Dev.to tutorial Sep 24

Can an AI Agent Know When Not to Act? A Fail-Closed Reliability Benchmark Across Six Models

A deterministic fail-closed benchmark testing evidence, approvals, tool truthfulness, secret handling, recovery, and stale-state detection across six AI models.

Agents Benchmark
12
Papers with Code paper Sep 24

RGBD20K: A Large-Scale Benchmark for RGB-D Semantic Segmentation

In this paper, we propose RGBD20K, a novel dataset for facilitating the development of more robust and general RGB-D semantic segmentation by encompassing abundant categories and h...

Benchmark
21
Dev.to tutorial Sep 23

Your LLM eval set is quietly certifying your bugs

Everyone eventually wants to build their LLM eval set from real traffic. It's the right instinct —...

LLM Benchmark
12
Mastodon discussion Sep 23

FinFIRST is a benchmark that evaluates financial search agents on answer quality and supporting evidence.Source: arXiv c...

FinFIRST is a benchmark that evaluates financial search agents on answer quality and supporting evidence.Source: arXiv cs.CLhttps://arxiv.org/abs/2609.25192#MachineLearning

Benchmark
9
Mastodon discussion Sep 23

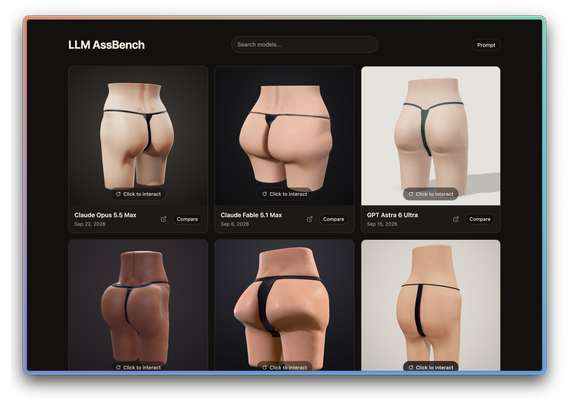
Je vous laisse libre de juger de la qualité de ce benchmark de LLM ... ⬇️https://www.assbench.com/#MachineLearning #AI📬 ...

Je vous laisse libre de juger de la qualité de ce benchmark de LLM ... ⬇️https://www.assbench.com/#MachineLearning #AI📬 Ma veille dev, chaque vendredi par email → https://l.camille...

LLM Benchmark
9
Mastodon discussion Sep 23

I built three Claude Code skills for AI product managers (ai-pm-skills). One of them, /eval-plan,...#ai #claude #product...

I built three Claude Code skills for AI product managers (ai-pm-skills). One of them, /eval-plan,...#ai #claude #productmanagement #testing #software #coding #development #engineer...

Anthropic Benchmark
24
Mastodon discussion Sep 23

📊 Solar Pro 2 (Preview) (Non-reasoning) — the actual numbers GPQA: 54.4% MMLU-Pro: 72.5% Humanity's Last Exam: 3.7% Live...

📊 Solar Pro 2 (Preview) (Non-reasoning) — the actual numbers GPQA: 54.4% MMLU-Pro: 72.5% Humanity's Last Exam: 3.7% LiveCodeBench: 38.5%Measured independently, not self-reported →h...

Benchmark
18
Mastodon discussion Sep 22

#Anthropic just dropped #Claude Opus 5.5, skipping a few released numbers ahead.And with good reason: improved benchmark...

#Anthropic just dropped #Claude Opus 5.5, skipping a few released numbers ahead.And with good reason: improved benchmarks, reduced costs, increased speed—all the topics we wanted t...

Anthropic Benchmark
9
Mastodon discussion Sep 22

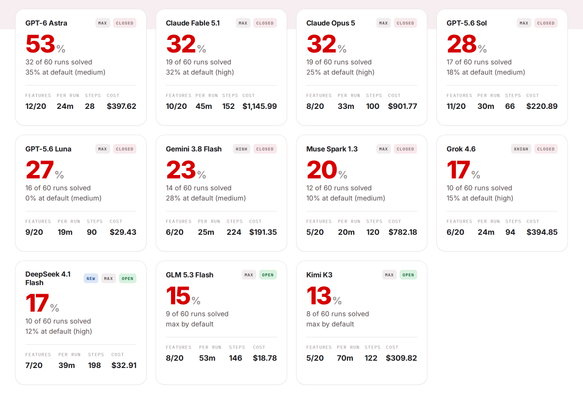
Nouveau round du benchmark Agents on Rails, reasoning poussé à fond. GPT-6 Astra grimpe à 53%, GPT-5.6 Luna passe de 0 à...

Nouveau round du benchmark Agents on Rails, reasoning poussé à fond. GPT-6 Astra grimpe à 53%, GPT-5.6 Luna passe de 0 à 27% pour 29 dollars. Claude Fable 5.1 stagne à 32% en doubl...

OpenAI Anthropic Benchmark
9
Mastodon discussion Sep 22

GPT-6 Astra cut costs per task but raised real-world AI spend 60% as engineers used it more — plus new agent eval toolin...

GPT-6 Astra cut costs per task but raised real-world AI spend 60% as engineers used it more — plus new agent eval tooling, a $40M liability bet, and data on AI app quality.https://...

OpenAI Benchmark
9
Mastodon discussion Sep 22

A step-by-step look at how an LLM benchmark produces comparable numbers, using the Satellite Geo QCM leaderboard as a co...

A step-by-step look at how an LLM benchmark produces comparable numbers, using the Satellite Geo QCM leaderboard as a concrete example of deterministic llm evaluation.#llm #evaluat...

LLM Benchmark
18
Mastodon discussion Sep 22

The paper introduces PII-TRACE, a benchmark for context-aware personally identifiable information detection in multi-tur...

The paper introduces PII-TRACE, a benchmark for context-aware personally identifiable information detection in multi-turn LLM conversations.Source: arXiv cs.CLhttps://arxiv.org/abs...

Benchmark
9
Dev.to tutorial Sep 22

Glasshouse v0.1 Is Out: A Memory Benchmark for AI Systems

Glasshouse v0.1 is out. It's a long-term memory benchmark for AI systems, and it's what my last two...

Benchmark
12
Mastodon discussion Sep 22

The study introduces PsyAgentBench, a benchmark that re-runs classic psychology experiments on large language model agen...

The study introduces PsyAgentBench, a benchmark that re-runs classic psychology experiments on large language model agents with a factorial design that varies paradigm labeling, ta...

LLM Benchmark
9
Dev.to tutorial Sep 22

Your AI eval is green because it never called the model

We run an eval suite on every PR. Seven fixtures, four metrics, deterministic, no API key, no...

Benchmark
12
Dev.to tutorial Sep 22

Designing an eval harness for prompt-injection detection: what measuring my defenses actually taught me

Designing an eval harness for prompt-injection detection: what measuring my defenses...

Benchmark
12
Mastodon discussion Sep 22

Designing an eval harness for prompt-injection detection: what measuring my defenses...#ai #security #llm #python #softw...

Designing an eval harness for prompt-injection detection: what measuring my defenses...#ai #security #llm #python #software #coding #development #engineering #inclusive #communityD...

LLM Benchmark
27
Mastodon discussion Sep 22

Grok 4.7 released (493 pts HN) — the open multimodal race heats up. What's interesting isn't the benchmark score but the...

Grok 4.7 released (493 pts HN) — the open multimodal race heats up. What's interesting isn't the benchmark score but the speed of release cycles; agents need current model catalogs...

xAI Multimodal Benchmark
9
AI Blogs (RSS) news Sep 22

How UK AISI and EvalEval Are Making Benchmark Results Reproducible

Benchmark
24
« Previous Page 19 of 70 (1676 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available