/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1677 articles tagged with Benchmark

Latest Trending
Mastodon discussion Aug 21

We introduce ClosureBench, a constructive benchmark for compositional graph-relational reasoning with programmatically v...

We introduce ClosureBench, a constructive benchmark for compositional graph-relational reasoning with programmatically verified ground truth. Unlike fixed-test-set benchmarks vulne...

Benchmark
9
Mastodon discussion Aug 21

GulliBench is a benchmark that purports to measure the "gullibility" of AI models.Here's there most "gullible" top 10:1....

GulliBench is a benchmark that purports to measure the "gullibility" of AI models.Here's there most "gullible" top 10:1. Opus 5 - 492. Fable 5 - 483. Muse Spark 1.2 - 424. Gemini 3...

Google Benchmark
18
NewsData.io news Aug 21

Hong Kong’s stock benchmark may see more tech additions as review result looms

More artificial intelligence companies may join the Hang Seng Index to increase the benchmark’s weighting towards technology, as the index compiler is due to reveal the result of i...

Benchmark
21
AI Blogs (RSS) news Aug 21

Measuring benchmark optimization in speech recognition

Benchmark
24
Papers with Code paper Aug 21

OmniAssistBench: Assistant-style Interaction Benchmark for Omni-LLMs

Recent omni-modal large language models (Omni-LLMs) show great potential as real-time video assistants, which continuously perceive environments and guide users to achieve specific...

Benchmark
21
Dev.to tutorial Aug 20

acc vs acc_norm: Why Length Bias Skews LLM Eval Scores

Why acc and acc_norm disagree in lm-eval-harness: log-likelihood length bias, byte-length normalization, and when each multiple-choice metric lies.

LLM Benchmark
12
Mastodon discussion Aug 20

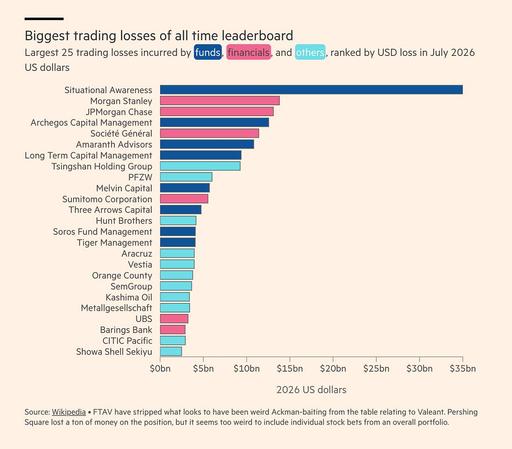
“the losses generated by Aschenbrenner’s leveraged #AI #stock #bets put him up at the top of the global leaderboard of #...

“the losses generated by Aschenbrenner’s leveraged #AI #stock #bets put him up at the top of the global leaderboard of #fundfacepalms. We know this because we found a cool table on...

Benchmark
9
Mastodon discussion Aug 20

📦 Fresh open weights on the leaderboard: Qwen3.8 27B (Alibaba)Context: 1M tokens · $0.45 in / $3.2 out per 1M · open wei...

📦 Fresh open weights on the leaderboard: Qwen3.8 27B (Alibaba)Context: 1M tokens · $0.45 in / $3.2 out per 1M · open weightsAll the latest models, tracked hourly:https://olud.ai/la...

Benchmark
9
Dev.to tutorial Aug 20

How I actually eval AI code review tools (no vendor numbers)

Every AI code review tool ships a blog post full of precision numbers. "98% precision, 87% recall,...

Benchmark
12
Dev.to tutorial Aug 20

oh-my-agent: cross-vendor refactor guards and isolated eval

oh-my-agent 12.4.0 just shipped with a cross-vendor refactor guard and isolated harness evaluation....

Benchmark
12
Papers with Code paper Aug 20

Towards Quantifying Benchmark Optimization in ASR Models

Public benchmarks are important measures of Automatic Speech Recognition (ASR) model capabilities. However, by nature of being public, there is risk of models being optimized for t...

Benchmark
21
Papers with Code paper Aug 20

One Success Isn't Reliability: Thinkingbox, a Sandbox and Benchmark for Agents in Stateful Business Workflows

Recent agent benchmarks increasingly ground evaluation in executable environments, from code repair to web navigation, app APIs, and function calling. Yet completing consequential ...

Benchmark
21
Mastodon discussion Aug 20

🤖 An AI agent just stacked blocks in a live physics simulation — building an open benchmark arena for embodied AISharing...

🤖 An AI agent just stacked blocks in a live physics simulation — building an open benchmark arena for embodied AISharing an early result from a project I'm building: an open, brows...

Agents Benchmark
9
NewsData.io news Aug 19

Apodex Launches TRACES, a Benchmark for Scientific Discovery

TRACES moves beyond static datasets and answer keys, testing whether AI can navigate real-world scientific environments, adapt to feedback and produce verifiable discoveries REDWOO...

Benchmark
21
Mastodon discussion Aug 19

📊 Mistral Large 2 (Nov '24) — the actual numbers GPQA: 48.6% MMLU-Pro: 69.7% Humanity's Last Exam: 3.3% Long Context Rea...

📊 Mistral Large 2 (Nov '24) — the actual numbers GPQA: 48.6% MMLU-Pro: 69.7% Humanity's Last Exam: 3.3% Long Context Reasoning: 5.3%Measured independently, not self-reported →https...

Mistral Benchmark
9
Papers with Code paper Aug 19

FM-Bench: A Benchmark for Long-Horizon Management with Competing Agents

Language model agents now execute bounded tasks reliably. Whether they can sustain effective decision-making over long horizons, where actions have cumulative consequences and the ...

Benchmark
21
Papers with Code paper Aug 19

SoftVTBench: A Deformation-Aware Visuo-Tactile Dataset and Benchmark for Deformable-Object Manipulation

Physical interaction quality is central to deformable-object manipulation, yet most benchmarks evaluate task success alone. A policy may complete the task while allowing slip or ca...

Benchmark Robotics
21
Mastodon discussion Aug 18

The mere fact that there's ANY change in #LLM behavior, ANY hint of improvement (if you cherry-pick the right #benchmark...

The mere fact that there's ANY change in #LLM behavior, ANY hint of improvement (if you cherry-pick the right #benchmark tests, for geeklords are positively addicted to meaningless...

LLM Benchmark
9
Dev.to tutorial Aug 18

Verify a signed VLA red-team leaderboard yourself, on CPU, in two commands

Provael publishes a leaderboard of attack success rates against vision-language-action robot...

Benchmark
12
Papers with Code paper Aug 18

HarnessRisk: A Lifecycle-Oriented Benchmark for Agent Harness Safety

Large language models are increasingly deployed through agent harnesses that manage tools, extensions, persistent state, permissions, and external actions. Existing safety benchmar...

Benchmark
21
Papers with Code paper Aug 18

PTXBench: Benchmark and Adapt LLMs for GPU Kernel Optimization with Architecture-specific PTX

We introduce PTXBench, a benchmark for evaluating and adapting large language models (LLMs) to use architecture-specific PTX for GPU kernel optimization. PTXBench measures function...

Benchmark AI Hardware
21
Dev.to tutorial Aug 17

Your Eval Suite Measures the Wrong Thing

Everyone measures whether the agent works. Almost nobody measures whether they'd know if it...

Benchmark
12
Dev.to tutorial Aug 17

Introducing Ayeixa Sentience Eval: Catching Raw JSON Leaks & Robotic Clichés in Agent Dialogue

Introducing Ayeixa Sentience Eval: Catching Raw JSON Leaks & Robotic Clichés in Agent...

Benchmark
12
Mastodon discussion Aug 17

Z.​ai has released GLM-5.3, claiming the top spot from Anthropic and OpenAI on the CyberGym benchmark.But before upgradi...

Z.​ai has released GLM-5.3, claiming the top spot from Anthropic and OpenAI on the CyberGym benchmark.But before upgrading, look at the fine print on active exploitation: https://w...

OpenAI Anthropic Benchmark
18
« Previous Page 30 of 70 (1677 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available