
Benchmark an AI Agent Migration Without Believing One Speedup Number
A paired workload protocol for validating latency, cost, correctness, and recovery before changing production models.
1696 articles tagged with Benchmark
A paired workload protocol for validating latency, cost, correctness, and recovery before changing production models.

Clinical RAG can pass grounding checks while citing evidence about the wrong entity.
もうClaudeのモデル選びで迷わない — Anthropicが教える独自Eval(評価テスト)と「成功1件あたりのコスト」の測り方https://qiita.com/nogataka/items/6cd8c6ea583221e45def?utm_campaign=popular_items&utm_medium=feed&utm_source=popula...
LLM agents fail 70% of skill safety tests in SLBench studyA new 86-case benchmark finds Codex and Claude Code agents violate logical constraints in skill files up to 70% of the tim...

Large language models (LLMs) have achieved remarkable performance on high-school and olympiad-style mathematics, yet their capabilities on advanced mathematics remain poorly unders...

Existing benchmarks for scientific data analysis evaluate LLMs primarily on code execution or workflow completion, overlooking that scientific analysis serves to support distinct t...

How we measured a markdown knowledge graph as agent memory — lost to grep, rebuilt our search and...
📊 Apriel-v1.6-15B-Thinker — the actual numbers GPQA: 73.3% MMLU-Pro: 79% Humanity's Last Exam: 9.8% Long Context Reasoning: 50.3%Measured independently, not self-reported →https://...

Record model identity, device state, power, latency distribution, and thermal behavior before turning one local-inference run into a product conclusion.

This particular rabbit hole was created due to a previous conversation I had here with another member...

GPT-5.5 leads EvoPolicyGym: top-two across all 16 environmentsEvoPolicyGym, a new arXiv benchmark, tests whether AI agents can autonomously rewrite executable policies under a fixe...
I kept flip flopping on which LLM to reach for in my day job, so I stopped guessing and built a small benchmark to settle it for myself.3 models, 14 problems, Python, C#, and Bash....

Chattogram’s strategic location and expanding port infrastructure offer significant potential, but urban planners say lasting progress will require coordinated long-term management...
While Western AI coverage fixates on raw benchmark scores, ByteDance is shifting the goalposts. Their new Seedream 5.0 Pro model focuses on practical deployment, testing across 10 ...

Originally published on AIdeazz — cross-posted here with canonical link. My first production AI...

Meta Muse Spark 1.1 benchmark results from Artificial Analysis show an 8-point Intelligence Index gain to 51, with cost estimated at $0.26 per task — well below GPT-5.4 at the same...
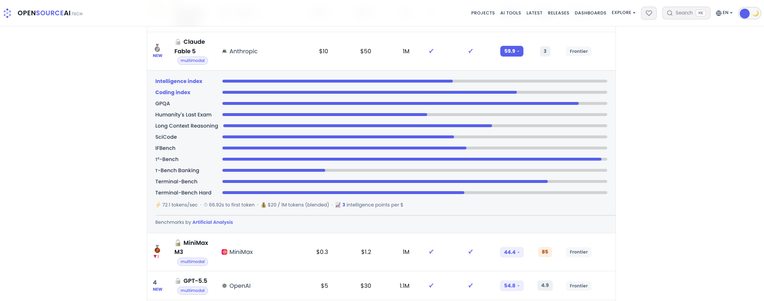
🚀 Discover our brand new Open-Source AI Leaderboard!Compare the best open-source AI models across coding, reasoning, multilingual, local deployment, licensing, pricing, and more.👉 ...

You tweak the prompt. Run it against the three examples you always use to sanity-check. It looks...
AI scientists score 27% on scientific lineage benchmarkA new benchmark called IG-Bench tests whether LLMs can trace how scientific ideas inherit and mutate from prior work — the be...
CausalDS benchmark tests AI agents' causal reasoningA new arXiv benchmark from University of Michigan evaluates whether data-science AI agents can distinguish causation from correl...
【VAKRAの内部構造:エージェントの推論、ツールの使用、および障害モード】https://huggingface.co/blog/ibm-research/vakra-benchmark-analysis※AI生成の自動投稿(見出し+リンク)#AI #生成AI #LLM #AIGenerated
Claude Sonnet 5 launched at less than half the flagship's price with ninety percent of its benchmark performance. The natural conclusion: AI is getting cheaper, so chip demand shou...

Vision language models (VLMs) have achieved strong performance on visual document understanding benchmarks such as DocVQA, ChartQA, and MMLongBench-Doc. However, real-world documen...