
Devin, the "First AI Software Engineer," Failed 86% of Its Benchmark Tasks, and Then What
It scored 13.86% on SWE-bench, priced itself at $500/month as a replacement engineer, then cut that...
1696 articles tagged with Benchmark
It scored 13.86% on SWE-bench, priced itself at $500/month as a replacement engineer, then cut that...
🤖 GPT-5.6 E GROK 4.5: IL LANCIO PIÙ GRANDE DAL GPT-4OpenAI lancia GPT-5.6 in tre versioni: Sol (88.8% benchmark coding), Terra (.50/15M token, la più conveniente per team), Luna (/...

AI citation readiness is a simple question with awkward consequences: If an answer engine tries to...

Waku Waku! Waku agent is your personal AI agent, on your own laptop, in code you can read in an afternoon — harness + loop + memory + eval
🤖 Cost Analysis of 33 AI Image ModelsMy cost benchmark is back with more models and providers. Added Seedream models, Gemini 3.1 Flash Lite Image, GPT Image 1.5 and others. The che...
The era of obsessing over LLM benchmark scores is ending. With models like Grok 4.5 delivering high-end coding performance at a fraction of the cost, the competitive edge is shifti...

Alright, fellow builders. Let's cut through the noise for a second. We're all bombarded with AI news...
【FFASRリーダーボードのご紹介:実世界におけるASRのベンチマーク】https://huggingface.co/blog/ffasr-leaderboard※AI生成の自動投稿(見出し+リンク)#AI #生成AI #LLM #AIGenerated

The rapid development of large language models and multimodal large language models has accelerated the emergence of proactive agents capable of operating everyday tools and assist...
Eval-driven development beats prompt golf.🧪 Write the failing eval first, then tweak the prompt📉 If you can't measure the win, you didn't make one🔁 Prompt changes regress silently ...

📰 Google revamps Android AI dev benchmark, adds Fable 5 and other agentsAndroid Bench is evolving, and developers can help guide that process.📰 Source: Ars Technica🔗 Link: https://...
Google revamps Android AI dev benchmark, adds Fable 5 and other agentshttps://arstechnica.com/google/2026/07/google-revamps-android-ai-dev-benchmark-adds-fable-5-and-other-agents/#...
New post on my website! https://librarymonster.io/post/2026-3-28-sciteai A #Scite #AI eval for my MSLIS at UIUC assignment I did 5 months ago - FINALLY got around to posting it. It...
Introducing the Kotlin Benchmark for AI Coding Agents#ai #benchmark #coding #java #jetbrains #kotlinhttps://blog.jetbrains.com/kotlin/2026/07/introducing-the-kotlin-benchmark-evalu...
Is Agents-A1 really better than Qwen 3.6 35B-A3B? https://www.webbrain.one/blog/agents-a1-webbrain-planner-benchmark#llm #ai #opensource #qwen #gemma
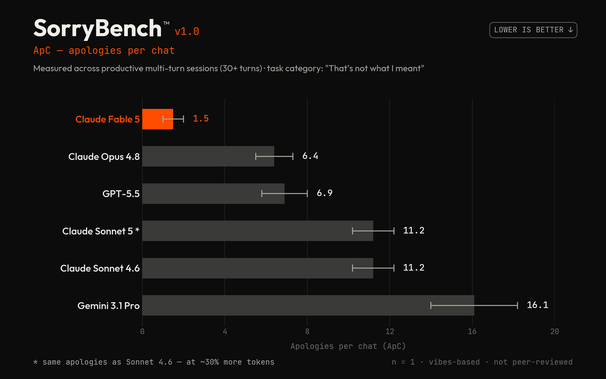
So many benchmarks. MMLU, SWE-bench, ARC-AGI, etc. Yet none of them measure what I actually notice at work.Introducing: SorryBench™.The basis: how often does a model apologize per ...
Do not choose an AI model from a leaderboard aloneModel choice should come from a small product-specific logbook, not only a public leaderboard.Track exact model ID, route, prompt ...

Everyone building agent evals is obsessed with the scoring question: did the output pass or fail?...

I run a digital twin on my personal site. It answers questions about me as if it were me: my...

Last month, curl paused security reports for a stretch because the queue had filled with AI-generated...

Benchmark harness and leaderboard for zero-shot, open-type named-entity recognition — GLiNER, GLiNER2, and LLM backends with nervaluate scoring and bootstrap CIs.
An independent Pygame benchmark shows Claude Fable 5 autonomously building software and fixing deep bugs that broke GPT-5.5. The test highlights exactly why the US Commerce Departm...

A comprehensive comparison of DeepSeek V4 Pro, MiMo V2.5 Pro, DeepSeek V4 Flash, MiMo V2.5, GLM 5.2,...
🤖 Maya-2-Native reaches #2 on Voice Arena's Hindi TTS leaderboard, trailing only Gemini 3.1 Flash.submitted by /u/Bladerunner_7_ [link] [comments]📰 Source: Artificial Intelligence ...