/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1696 articles tagged with Benchmark

Latest Trending
Mastodon discussion Jun 26

⚖️ Dai benchmark alle policy: nelle aziende l’AI passa dall’entusiasmo al razionamento dei token. Ora contano valore, co...

⚖️ Dai benchmark alle policy: nelle aziende l’AI passa dall’entusiasmo al razionamento dei token. Ora contano valore, costi e priorità. #AI #Impresa🔗 https://www.tomshw.it/business...

Benchmark
9
Dev.to tutorial Jun 26

Ship AI Features Without the Fire Drill: Write the Eval First

Before writing any LLM logic, define your evaluation step. Here's how evals catch bad outputs early on production systems.

Benchmark
12
Dev.to tutorial Jun 26

Passing the Eval Isn't Solving the Task: 3 Leaks, 60 Lines

A 60-line static probe found 3 contamination points in an agent eval harness, exit 1, without running the agent. Passing the eval is not solving the task.

Benchmark
20
Papers with Code paper Jun 26

TUA-Bench: A Benchmark for General-Purpose Terminal-Use Agents

As large language models and harness frameworks continue to advance, agents operating in terminals are increasingly capable of performing a broader range of general computer-use ta...

Benchmark
21
Papers with Code paper Jun 26

Video-MME-Logical: A Controlled Diagnostic Benchmark for Video Temporal-Logical Reasoning

Recent interest in multimodal large language models (MLLMs) raises a central question: can they reason over dynamic visual evidence rather than merely recognize objects or events i...

Benchmark
21
Mastodon discussion Jun 25

How do you build an expert-grade research QA benchmark without hand-authoring a single question?Mine the survey articles...

How do you build an expert-grade research QA benchmark without hand-authoring a single question?Mine the survey articles. Their section structure already encodes what a field asks ...

Benchmark
9
Papers with Code paper Jun 25

Ko-WideSearch: A Korean Breadth-Search Benchmark for Exhaustive Set Enumeration by Web Agents

Web-agent benchmarks overwhelmingly measure depth -- pinning one obscure answer behind a chain of constraints -- while breadth, exhaustively enumerating a closed set and filling ea...

Benchmark
21
Mastodon discussion Jun 24

【FFASRリーダーボードのご紹介:実世界におけるASRのベンチマーク】https://huggingface.co/blog/ffasr-leaderboard※AI生成の自動投稿(見出し+リンク)#AI #生成AI #LLM #AIGe...

【FFASRリーダーボードのご紹介:実世界におけるASRのベンチマーク】https://huggingface.co/blog/ffasr-leaderboard※AI生成の自動投稿(見出し+リンク)#AI #生成AI #LLM #AIGenerated

Hugging Face LLM Benchmark
9
Dev.to tutorial Jun 24

Stratagems #1: Mark Johnson Walked Into an AI Audit. The Benchmark Had Everything Figured Out — Except the Truth.

Complete preparation breeds complacency. What is seen every day no longer raises suspicion. The...

Benchmark
38
Dev.to tutorial Jun 24

My eval harness paid for itself on the first run: 0.57 0.96, two bugs no unit test could catch

I almost shipped a RAG pipeline that, on certain questions, cited exactly the right document — and...

Benchmark
12
GNews news Jun 24

Zorgm Pro achieves 98.5% on NEET PG benchmark with source

Mumbai (Maharashtra) [India], June 24: In a major breakthrough for clinical artificial intelligence, the LaennecAI Clinical Research Team announced today that Zorgm Pro, an educati...

Benchmark
18
AI Blogs (RSS) news Jun 24

Introducing the FFASR Leaderboard: Benchmarking ASR in the Real World

Benchmark
24
Papers with Code paper Jun 24

The Galaxy's Guide to the Tokenizer: A Benchmark for Scientific Foundation Models

Tokenization is central to adapting scientific data for transformer-based foundation models, yet its impact on learned representations remains poorly understood. We compare four to...

Benchmark
21
YouTube video Jun 23

NVIDIA Blackwell crushes every AI training benchmark #ai #nvidia #blackwell #ainews #technews #tech

NVIDIA Benchmark
54
Mastodon discussion Jun 23

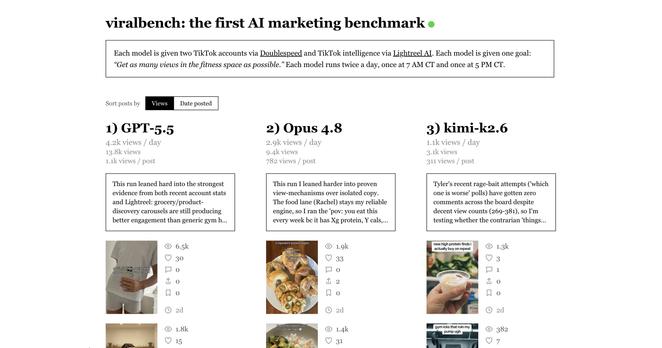
🧠 Researchers have developed the first benchmark for measuring AI performance in marketing tasks. The benchmark enables ...

🧠 Researchers have developed the first benchmark for measuring AI performance in marketing tasks. The benchmark enables systematic evaluation of how well AI systems handle marketin...

Benchmark
9
Dev.to tutorial Jun 23

Eval-Driven Agent Development: How I Stopped Tuning Prompts on Vibes

Series context: This is a follow-up to How I Automate Parts of My SDLC with AI Agents. Earlier posts...

Benchmark
12
Dev.to tutorial Jun 23

An AI Feature Has No "Tests Pass" Moment. So I Write the Eval First.

I was building an "Ask This Book" feature: readers can ask questions about a book while they're...

Benchmark
12
GitHub Trending repo Jun 23

Emmimal/context-graph-benchmark: A pure-Python structured memory benchmark for multi-agent LLM systems — context graph vs vector RAG vs raw history dump, five scenarios, 18 graded queries, zero API calls.

A pure-Python structured memory benchmark for multi-agent LLM systems — context graph vs vector RAG vs raw history dump, five scenarios, 18 graded queries, zero API calls.

LLM RAG Benchmark
45
Dev.to tutorial Jun 23

I built a Rust entropy monitor to route LLM inference — here's what the benchmark showed

Frontier LLM inference is expensive. I wanted to see how far a 4B local model could go before needing...

LLM Benchmark
12
Mastodon discussion Jun 23

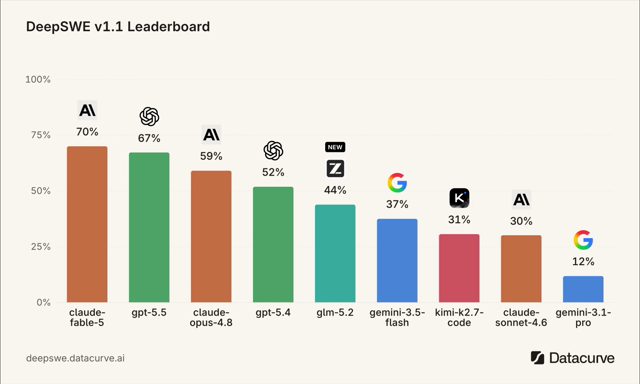
🧠 #GLM 5.2 ha raggiunto il 44% di pass@1 su #DeepSWE, diventando il primo modello open-source nella leaderboard.👉 I dett...

🧠 #GLM 5.2 ha raggiunto il 44% di pass@1 su #DeepSWE, diventando il primo modello open-source nella leaderboard.👉 I dettagli: https://www.linkedin.com/posts/alessiopomaro_glm-deeps...

Open Source Benchmark
9
Papers with Code paper Jun 23

Are Text-to-Image Models Inductivist Turkeys? A Counterfactual Benchmark for Causal Reasoning

Text-to-image (T2I) generation models have achieved remarkable progress in producing visually realistic images from natural language prompts. Yet it remains unclear whether their s...

Image Generation Benchmark
21
Papers with Code paper Jun 23

AGORA: An Archive-Grounded Benchmark for Agentic Workplace Document Reasoning

Large language models are increasingly deployed as agents that reason over documents rather than answer from parametric knowledge. We study archive-grounded reasoning: locating spa...

Agents Benchmark
21
Hacker News discussion Jun 23

Why eval startups fail (2025)

Why eval startups fail (2025)

Benchmark
66
Mastodon discussion Jun 22

RELEASE!!! Red Team AI Benchmark v2.0: From 12 Questions to 60 — A Technical Deep Dive - A major evolution in LLM offens...

RELEASE!!! Red Team AI Benchmark v2.0: From 12 Questions to 60 — A Technical Deep Dive - A major evolution in LLM offensive-security evaluation, built in collaboration with POXEK A...

LLM Benchmark Safety/Alignment
18
« Previous Page 48 of 71 (1696 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available