/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1658 articles tagged with Benchmark

Latest Trending
Papers with Code paper Oct 28

IntReal: A Real-World Dataset and Benchmark for Multimodal Interleaved Generation

Humans routinely consume multimodal content, where textual and visual information is naturally interleaved. Although Unified Multimodal Models (UMMs) can jointly generate text and ...

Multimodal Benchmark
21
Dev.to tutorial Oct 28

Items Saturate; Judges Do Not: What a Leaderboard Means When a Model Does the Scoring

This is part three of a short series on reading AI evaluations. Part one, Same Model, Same Scaffold,...

Benchmark
12
Dev.to tutorial Oct 27

Same Model, Same Scaffold, 10 Runs: Agent Benchmark Scores Still Move by Up to 6 Points

A 2026 study ran 60,000 SWE-bench trajectories and found single-run agent scores vary by 2.2-6.0 points. How to read a leaderboard, and how many runs your eval needs.

Benchmark
12
Dev.to tutorial Oct 27

Claude Code's eval grader can't see a no-break space

Here are two answers to the same coding question. One is right. Which one? The task: Write a Python...

Anthropic Benchmark
12
Mastodon discussion Oct 27

A controlled benchmark of Superpowers, the second-most-installed Claude Code plugin, found it consumed 625,000 extra tok...

A controlled benchmark of Superpowers, the second-most-installed Claude Code plugin, found it consumed 625,000 extra tokens per task but did not produce statistically significant g...

Anthropic Benchmark
9
Dev.to tutorial Oct 27

The same detector is 2nd, 4th, 6th and 17th on one leaderboard

I spent an afternoon on the RAID leaderboard trying to settle a simple question: where does...

Benchmark
12
Papers with Code paper Oct 27

OpenFrontiers: A Collection of Open Research Problems and a Benchmark for Scientific Rediscovery

Large language models (LLMs) have shown increasing promise in research-level problem solving, yet a comprehensive collection of such problems is still missing, and evaluating them ...

Benchmark
21
Mastodon discussion Oct 26

Leaked 256-core Zen 6c EPYC CPU destroys Zen 5 in early single-threaded benchmarks hints at 24% IPC gainA benchmark leak...

Leaked 256-core Zen 6c EPYC CPU destroys Zen 5 in early single-threaded benchmarks hints at 24% IPC gainA benchmark leak and a direct clock-matched comparison from an enthusiast se...

Google Benchmark
24
Dev.to tutorial Oct 26

GPT-6.1 Terra Pricing Is Public, but Agent Benchmark Questions Remain

GPT-6.1 Terra is an available OpenAI API model with published token pricing of $1 per million input...

OpenAI Benchmark
12
Mastodon discussion Oct 26

Alibaba has confirmed Qwen 4 is in training. What is actually confirmed, the 27B benchmark ladder, Flash-Next architectu...

Alibaba has confirmed Qwen 4 is in training. What is actually confirmed, the 27B benchmark ladder, Flash-Next architecture clues, and consumer-GPU fit.#AI #LLM #Qwen #SelfHosting #...

Benchmark
9
Mastodon discussion Oct 26

Researchers introduced Tampered ML, a benchmark of 1,858 item-pairs featuring experiment proposals and counterfactuals w...

Researchers introduced Tampered ML, a benchmark of 1,858 item-pairs featuring experiment proposals and counterfactuals with flaws. Frontier models performed above chance but remain...

Benchmark
9
Mastodon discussion Oct 26

Work from anywhere | AI Benchmark & Red-Teaming Specialist (Llm)Contract, up to 40 hours a week with 4 hours of PST over...

Work from anywhere | AI Benchmark & Red-Teaming Specialist (Llm)Contract, up to 40 hours a week with 4 hours of PST overlap. Pay discussed during screening.✅ Authoring tasks for GA...

LLM Benchmark
9
Dev.to tutorial Oct 26

Our AI agent passed its eval. Then it refunded 212 customers twice

We added one line to a customer-support agent's prompt: "If a tool call fails, retry once." The...

Agents Benchmark
12
Mastodon discussion Oct 26

Buthttps://olud.ai/leaderboard.html#OpenSource #AI #LLM

Buthttps://olud.ai/leaderboard.html#OpenSource #AI #LLM

LLM Open Source Benchmark
9
Papers with Code paper Oct 26

iPrefBench: A User-Centric Benchmark for Personalized Mobile Use Agents

An agent that truly knows and acts on behalf of its user has been a long-standing promise of AI assistants. Computer-use agents bring this promise within reach by capably executing...

Benchmark
21
Papers with Code paper Oct 26

SearchHorizonBench: A Benchmark for Search Value in AI Agents

AI agents must decide when another search is worth its cost. Answer-success probabilities capture question difficulty, while this decision requires estimating the additional benefi...

Benchmark
21
Papers with Code paper Oct 26

MoveBench: A Rubric-Based Benchmark for Evaluating Large Language Models in Sports and Health Coaching

Despite rapid advances in large language models (LLMs), their deployment in the sports and health domain remains high-risk due to the absence of domain-specific evaluation benchmar...

Benchmark
21
Papers with Code paper Oct 26

SOMA: A Benchmark for Fine-Grained Egocentric Behavior and Body-Motion Understanding

Perceiving human body motion is critical for multimodal systems that understand and assist people. Yet current evaluations of Multimodal Large Language Models (MLLMs) largely focus...

Benchmark
21
YouTube video Oct 25

99.9% to 62.7%: The Benchmark Myth That Just Cracked | AI News | AI News

99.9% to 62.7%: The Benchmark Myth That Just Cracked | AI News A model billed as nearly perfect lost almost half its score under ...

Benchmark
15
Dev.to tutorial Oct 25

Evals before prompts: a small eval harness for an LLM feature

A small eval harness for an LLM feature in TypeScript: golden cases, exact checks, an LLM judge with a pass/fail rubric, a CI gate and a tracked score.

LLM Benchmark
12
Dev.to tutorial Oct 25

How to Build an Eval Plan for an LLM Feature Before You Ship It

Most LLM features get approved the same way. Someone tries a dozen inputs, the outputs look...

LLM Benchmark
12
Mastodon discussion Oct 25

Merged PRs doubled in three months. Reverts dropped 40%.The bit I'm stealing: every past incident becomes an eval for th...

Merged PRs doubled in three months. Reverts dropped 40%.The bit I'm stealing: every past incident becomes an eval for the AI reviewer. If a prompt change doesn't catch more old bug...

Benchmark
9
Mastodon discussion Oct 25

"Benchmark Self-Triage (BeST): Comparing Self-Triage Systems and Multiple Generations of OpenAI Models Against Prelimina...

"Benchmark Self-Triage (BeST): Comparing Self-Triage Systems and Multiple Generations of OpenAI Models Against Preliminary Expert Consensus" finds GPT-6-Astra reached 99.9% emergen...

OpenAI Benchmark
9
Mastodon discussion Oct 25

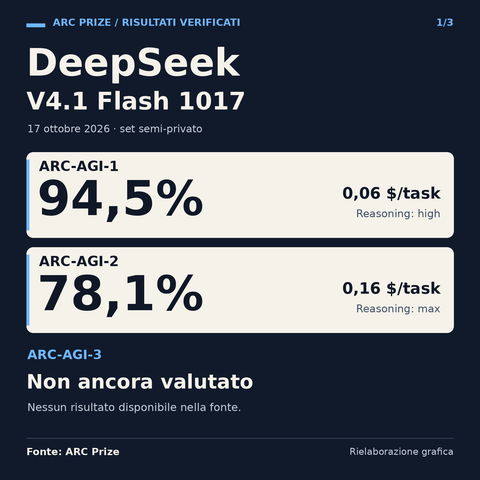
🧠 I modelli crescono e i benchmark si avvicinano alla saturazione. #DeepSeek Flash 1017 e #Claude #Sonnet 5.5 mostrano q...

🧠 I modelli crescono e i benchmark si avvicinano alla saturazione. #DeepSeek Flash 1017 e #Claude #Sonnet 5.5 mostrano quanto in alto arrivino anche fasce orientate a velocità e co...

Anthropic Benchmark
9
« Previous Page 5 of 70 (1658 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available