
QuitoBench: A High-Quality Open Time Series Forecasting Benchmark
Time series forecasting is critical across finance, healthcare, and cloud computing, yet progress is constrained by a fundamental bottleneck: the scarcity of large-scale, high-qual...
1698 articles tagged with Benchmark
Time series forecasting is critical across finance, healthcare, and cloud computing, yet progress is constrained by a fundamental bottleneck: the scarcity of large-scale, high-qual...
Recent advances in image generation models have expanded their applications beyond aesthetic imagery toward practical visual content creation. However, existing benchmarks mainly f...

Recent advances in image generation models have expanded their applications beyond aesthetic imagery toward practical visual content creation. However, existing benchmarks mainly f...
Aktuelle KI-Modelle scheitern beim ARC-AGI-3-Benchmark für interaktives Reasoning mit Erfolgsquoten unter 0,4 Prozent.Die Modelle scheitern an visuellen Transferleistungen, die unt...
End-to-end autonomous driving (E2E-AD) has achieved remarkable progress. However, one practical and useful function has been long overlooked: users may wish to customize the desire...
Claude skill that evaluates B2B vendors by talking to their AI agentshttps://github.com/salespeak-ai/buyer-eval-skill#HackerNews #Claude #B2B #vendors #AI #agents #evaluation #sale...
Accurate parsing of citations is necessary for machine-readable scholarly infrastructure. But, despite sustained interest in this problem, existing evaluation techniques are often ...

📰 ARC-AGI-3: AI Models Score Below 1% on Human-Like Tasks (2026 Benchmark)ARC-AGI-3 reveals that top AI models score under 1% on tasks humans solve effortlessly, exposing critical ...
OpenAI führt mit Model Spec Evals einen neuen Benchmark zur Messung der Regeltreue ein. Dabei schneidet das ältere GPT-5 Thinking mit 89 Prozent messbar besser ab als das aktuelle ...
Ego2Web Benchmark Bridges Egocentric Video and Web Agents, Exposing Major Performance GapsResearchers introduce Ego2Web, the first benchmark requiring AI agents to understand real-...

While Large Language Models (LLMs) achieve high performance on standard mathematical benchmarks, their underlying reasoning processes remain highly overfit to standard textual form...

Cursor just released this article and a ton of people started worshiping Cursor like they just made a...


📰 Qwen3.5-397B Hits 20 Tokens/sec on RTX 4090 — New LLM Benchmark Record (2026)A groundbreaking benchmark reveals Qwen3.5-397B achieves 20 tokens per second on a single RTX 5090 GP...
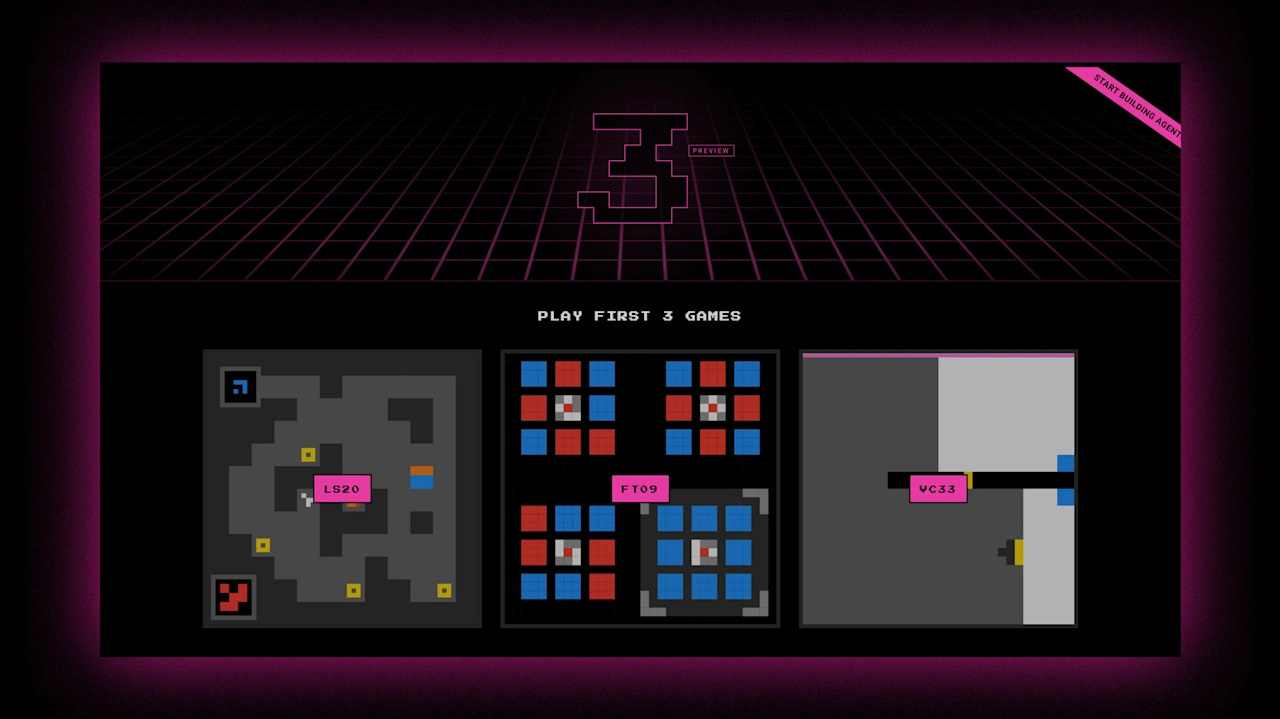
The influential AI researcher François Chollet has long argued that the field measures intelligence incorrectly, that popular benchmarks reward a model’s ability to memorize vast ...

📰 Embodied Arena Benchmark Topped by Huawei Genius Youth with X Square Robot — 2026A former Huawei 'Genius Youth' has launched a groundbreaking home robotics model that now leads t...

Understanding animal species from multimodal data poses an emerging challenge at the intersection of computer vision and ecology. While recent biological models, such as BioCLIP, h...

Large Language Models (LLMs) are increasingly used for code generation, yet quantum code generation is still evaluated mostly within single frameworks, making it difficult to separ...

Independent framework to test, benchmark, and evaluate LLMs & AI agents locally.

Large language models (LLMs) have enabled agentic systems that can reason, plan, and act across complex tasks, but it remains unclear whether they can allocate resources effectivel...
Software engineering agents have shown significant promise in writing code. As AI agents permeate code writing, and generate huge volumes of code automatically -- the matter of cod...
Seismic images reconstruct subsurface reflectivity from field recordings, guiding exploration and reservoir monitoring. Gas chimneys are vertical anomalies caused by subsurface flu...

Multimodal AI agents are increasingly automating complex real-world workflows that involve online web execution. However, current web-agent benchmarks suffer from a critical limita...

Subject-driven image generation is increasingly expected to support fine-grained control over multiple entities within a single image. In multi-reference workflows, users may provi...