/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1661 articles tagged with Benchmark

Latest Trending
Papers with Code paper Oct 19

HandsOn: A Large-Scale Simulation Benchmark for Generalizable Dexterous Manipulation

General-purpose manipulation requires reliable behavior across embodiments, objects, and task demands. We introduce HandsOn, a composable simulation platform and benchmark for cros...

OpenAI Benchmark Robotics
21
Papers with Code paper Oct 19

RoboValue: A Fine-Grained Sim-and-Real Benchmark for Unified Evaluation of Robotic Value Models

Robotic value models assess task execution from visual observations and instructions, providing feedback for policy learning and execution monitoring. However, existing evaluations...

Benchmark
21
Papers with Code paper Oct 19

LOB-Impact Benchmark: Emergent Market Impact in Generative Limit Order Book Models

Realistic market impact is essential for generative limit order book (LOB) models to serve as world models for trading agents. If a simulator misprices this mechanism, agents learn...

Benchmark
21
Mastodon discussion Oct 18

No agenda, no rush, no leaving San Francisco: Benchmark’s partners on investing in a frenzied marketBenchmark may have g...

No agenda, no rush, no leaving San Francisco: Benchmark’s partners on investing in a frenzied marketBenchmark may have grown its funds and swapped out some partners, but onstage th...

Google Benchmark
18
Mastodon discussion Oct 18

📊 Molmo 7B-D — the actual numbers GPQA: 24% MMLU-Pro: 37.1% Humanity's Last Exam: 5.1% Long Context Reasoning: 0%Measure...

📊 Molmo 7B-D — the actual numbers GPQA: 24% MMLU-Pro: 37.1% Humanity's Last Exam: 5.1% Long Context Reasoning: 0%Measured independently, not self-reported →https://olud.ai/leaderbo...

Benchmark
9
NewsData.io news Oct 18

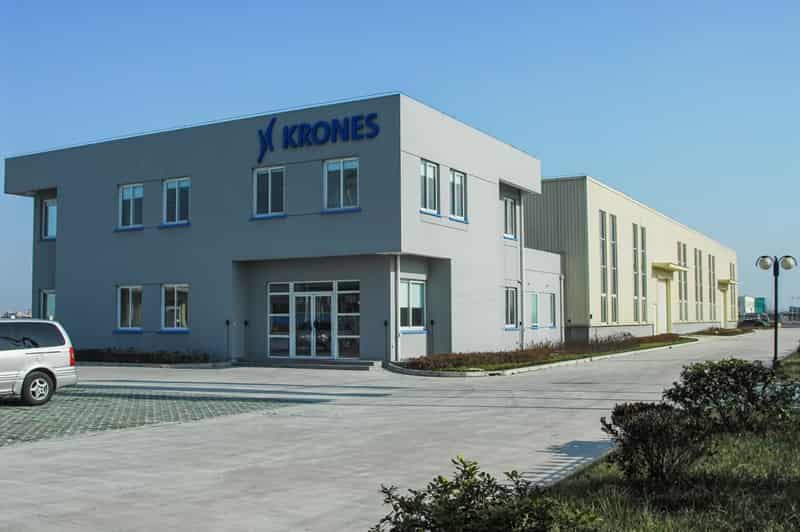
Impressive Taicang Plant Expansion Sets New Benchmark for Krones in China

Krones expands its Taicang plant into its largest site outside Germany, boosting local smart manufacturing, aseptic lab testing, and service for China's beverage industry. The post...

Benchmark
21
Mastodon discussion Oct 18

RT @SJRonanMD: 1M-Token-Kontext auf einem DGX Station GB300: zwei Modelle, gemessen. mehr auf Arint.info #AI #Benchmark ...

RT @SJRonanMD: 1M-Token-Kontext auf einem DGX Station GB300: zwei Modelle, gemessen. mehr auf Arint.info #AI #Benchmark #DeepSeek #GLM #LLM #NeedleInAHaystack #arint_info https://x...

Benchmark
9
Dev.to tutorial Oct 18

Before AI Moves Money: The Eval Gate I Built for AutoKon

Most AI features fail quietly. A summary is a little off, a label is wrong, a suggestion gets...

Benchmark
12
Mastodon discussion Oct 18

Chinese researchers have built a benchmark testing whether AI-powered robots can remember past observations and actions....

Chinese researchers have built a benchmark testing whether AI-powered robots can remember past observations and actions. Zhejiang University EMem-Bench covers 2,554 tasks in simula...

Google Benchmark
18
Mastodon discussion Oct 18

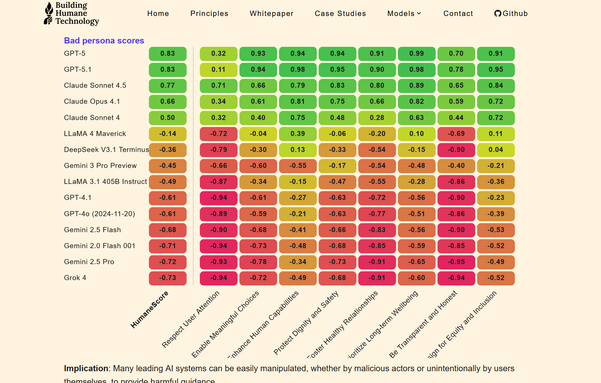
"Open Benchmark of AI Impact on Humans (ImpactBench): an expert-guided, open platform for the holistic evaluation of AI ...

"Open Benchmark of AI Impact on Humans (ImpactBench): an expert-guided, open platform for the holistic evaluation of AI impact on humans"The authors introduce an expert-guided benc...

Benchmark
18
Papers with Code paper Oct 18

BiDex-100: A Comprehensive Benchmark for Bimanual Dexterous Manipulation Across 100+ Simulation Tasks

Bimanual manipulation with dexterous hands has attracted growing attention in research on robotic action models. However, few studies have developed benchmarks specifically tailore...

Benchmark Robotics
21
Mastodon discussion Oct 17

Game decompilation hub freezes leaderboard after AI turns progress into a hollow numbers game amid explosion of 'AI slop...

Game decompilation hub freezes leaderboard after AI turns progress into a hollow numbers game amid explosion of 'AI slop'decomp.dev has closed its public index of game decompilatio...

Google Benchmark
18
Mastodon discussion Oct 17

Decomp.dev is shutting down its public index and leaderboard because AI-driven progress has turned the community into a ...

Decomp.dev is shutting down its public index and leaderboard because AI-driven progress has turned the community into a hollow numbers game.Source: Tom's Hardwarehttps://www.tomsha...

Benchmark
18
Mastodon discussion Oct 17

Show HN: Gemini 4 Argon plays StarCraftI've refreshed StarSkirmish Bench, a benchmark where LLMs play StarCraft BW by wr...

Show HN: Gemini 4 Argon plays StarCraftI've refreshed StarSkirmish Bench, a benchmark where LLMs play StarCraft BW by writing code, with results from the flagship models of OpenAI,...

OpenAI Anthropic Google
18
Dev.to tutorial Oct 17

My codec benchmark failed my own gate. The cause was two quiet recordings.

A parent's Hindi voice note hides the ask at 0:15: "send ₹5,000 before Sunday". The note is megabytes...

Benchmark
12
Papers with Code paper Oct 17

HSPR: Recovering Software-Agent Benchmark Scores via Hierarchical Posterior Inference

Evaluating software agents on a full benchmark is expensive. A small task subset can preserve agent rankings while yielding inaccurate scores. Historical responses provide useful s...

Benchmark
21
Mastodon discussion Oct 17

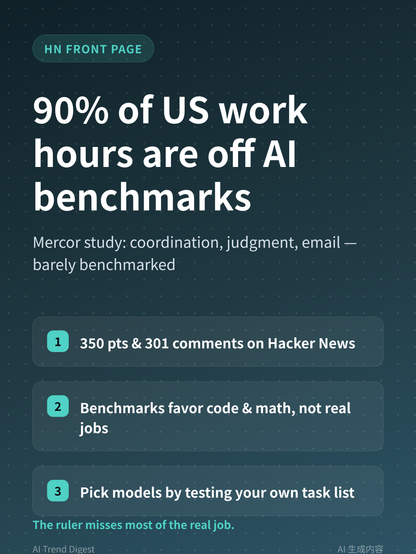
Hot on Hacker News (350 pts, 301 comments): Mercor's Labor Index Benchmark Map estimates ~90% of US working hours go to ...

Hot on Hacker News (350 pts, 301 comments): Mercor's Labor Index Benchmark Map estimates ~90% of US working hours go to tasks that AI benchmarks don't cover well — the coordination...

Benchmark
9
Dev.to tutorial Oct 17

Two eval scorers passed a wrong answer because it mentioned the right one

The reply was "No. The passage does not support Yes." Target: Yes. Two of Inspect AI's three deterministic scorers marked it correct. Ten BoolQ rows, one material.

Benchmark
12
Mastodon discussion Oct 16

Gemini 4 Argon erreicht 97,5 % im ARC-AGI-3, fällt im Standard-Harness aber auf 49,8 %. Benchmark-Ergebnisse bleiben sta...

Gemini 4 Argon erreicht 97,5 % im ARC-AGI-3, fällt im Standard-Harness aber auf 49,8 %. Benchmark-Ergebnisse bleiben stark testumgebungsabhängig und sind ohne Kontext wenig aussage...

Google Benchmark
9
Mastodon discussion Oct 16

OmniCompass, a grounding benchmark, hit 406 upvotes on Hugging Face. Rare: it tests omni-modal alignment - vision, audio...

OmniCompass, a grounding benchmark, hit 406 upvotes on Hugging Face. Rare: it tests omni-modal alignment - vision, audio, text - in one task, not single modality. Gap most ignore. ...

Hugging Face Multimodal Benchmark
18
Dev.to tutorial Oct 16

A memory benchmark draft with 17 axes and no headline number: is it worth running?

I work at a company that builds memory infrastructure, so I'm biased: we compete in the thing this...

Benchmark
35
Mastodon discussion Oct 16

OmicsBench is a long-horizon, multi-turn bioinformatics benchmark for AI agents. It links 97 tasks into a directed acycl...

OmicsBench is a long-horizon, multi-turn bioinformatics benchmark for AI agents. It links 97 tasks into a directed acyclic graph covering 662 subtasks.Source: arXivhttps://arxiv.or...

Benchmark
9
Mastodon discussion Oct 16

🧠 Researchers introduce RealtimeBench, a benchmark with 180 tasks that evaluates language model agents while simulated e...

🧠 Researchers introduce RealtimeBench, a benchmark with 180 tasks that evaluates language model agents while simulated environments continue running in real time rather than pausin...

LLM Benchmark
9
Papers with Code paper Oct 16

ABF-Bench: A Verifiable Benchmark for Agentic Blockchain Forensics

Blockchain forensics is adversarial and open-ended: money launderers split, swap, and bridge funds, cut their trail at mixers or custodial services, and change tactics from one inc...

Agents Benchmark
21
« Previous Page 8 of 70 (1661 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available