/// AI HUB
Dashboard News Models Tools Papers Repos Videos Companies Trending
Login

#Benchmark

1661 articles tagged with Benchmark

Latest Trending
Mastodon discussion Oct 16

DeepSeek V3 (Dec '24) — GPQA 55.7%, MMLU-Pro 75.2%, and 18.4 intelligence points per dollar. That efficiency at this acc...

DeepSeek V3 (Dec '24) — GPQA 55.7%, MMLU-Pro 75.2%, and 18.4 intelligence points per dollar. That efficiency at this accuracy is rare.https://olud.ai/leaderboard.html#LLM #Benchmar...
Benchmark
9
Mastodon discussion Oct 16

Le plus dur n'est pas d'ecrire un agent LLM, c'est de savoir quand il casse.Agent Eval Kit (19 USD) : 90 cas de test pre...

Le plus dur n'est pas d'ecrire un agent LLM, c'est de savoir quand il casse.Agent Eval Kit (19 USD) : 90 cas de test prets: 4 suites, runner multi-providers, score par run, seuil d...

LLM Benchmark
9
Mastodon discussion Oct 15

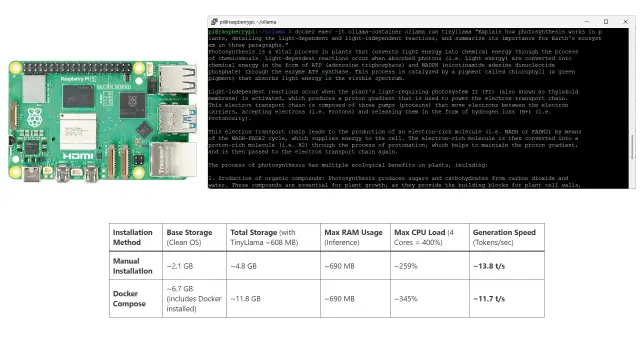
Want to run LLMs like TinyLlama or Llama 3 locally on a #RaspberryPi?I published a complete, hands-on benchmark comparin...

Want to run LLMs like TinyLlama or Llama 3 locally on a #RaspberryPi?I published a complete, hands-on benchmark comparing #Ollama Native vs #Docker Compose installations on Raspber...

Meta Benchmark
18
Mastodon discussion Oct 15

KoAGE introduces a cutoff-aware benchmark for Korean neologisms with three acquisition and two generation tasks. arXiv c...

KoAGE introduces a cutoff-aware benchmark for Korean neologisms with three acquisition and two generation tasks. arXiv cs.CLSource: arXiv cs.CLhttps://arxiv.org/abs/2610.19399#Mach...

Benchmark
9
Mastodon discussion Oct 15

Researchers introduced LePhilBench to evaluate legal-philosophical reasoning in large language models. The benchmark com...

Researchers introduced LePhilBench to evaluate legal-philosophical reasoning in large language models. The benchmark comprises two benchmarking tasks and a dataset.Source: arXiv cs...

Benchmark
9
Hugging Face tool Oct 15

joelniklaus/harness-leaderboard - AI Space/Demo

Hugging Face Space: joelniklaus/harness-leaderboard

Benchmark
63
Mastodon discussion Oct 15

Write string: "🎨 Qwen-Image-3.0-Prohttps://olud.ai/media-leaderboard.html#OpenSource #GenerativeAI #StableDiffusion #AI

Write string: "🎨 Qwen-Image-3.0-Prohttps://olud.ai/media-leaderboard.html#OpenSource #GenerativeAI #StableDiffusion #AI

Open Source Benchmark
9
NewsData.io news Oct 15

South Korea’s benchmark Kospi index sinks more than 7% as tech sell-off deepens

South Korea’s benchmark Kospi index has dropped by more than 7% as a sell-off of technology shares deepened after U.S. stocks fell on hotter-than-expected inflation data. The Kospi...

Benchmark
21
Mastodon discussion Oct 15

📊 Exaone 4.0 1.2B (Non-reasoning) — the actual numbers GPQA: 42.4% MMLU-Pro: 50% Humanity's Last Exam: 5.7% Long Context...

📊 Exaone 4.0 1.2B (Non-reasoning) — the actual numbers GPQA: 42.4% MMLU-Pro: 50% Humanity's Last Exam: 5.7% Long Context Reasoning: 0%Measured independently, not self-reported →htt...

Benchmark
9
Mastodon discussion Oct 14

🧠 Multiple AI models perform poorly on a newly introduced benchmark. The benchmark appears to present challenges that cu...

🧠 Multiple AI models perform poorly on a newly introduced benchmark. The benchmark appears to present challenges that current approaches have not successfully addressed.💬 Hacker Ne...

Benchmark
9
Mastodon discussion Oct 14

📦 Fresh on the leaderboard: Gemini 4 Argon (Google)Context: 1M tokens · $2 in / $10 out per 1M · commercialAll the lates...

📦 Fresh on the leaderboard: Gemini 4 Argon (Google)Context: 1M tokens · $2 in / $10 out per 1M · commercialAll the latest models, tracked hourly:https://olud.ai/latest.html#AI #LLM

Google Benchmark
9
Mastodon discussion Oct 14

Artemis Security stellt Orion-1 vor, ein KI-Modell für Cyberabwehr, das im eigenen Benchmark Claude Opus 5.5 und GPT-6 S...

Artemis Security stellt Orion-1 vor, ein KI-Modell für Cyberabwehr, das im eigenen Benchmark Claude Opus 5.5 und GPT-6 Sol übertreffen soll. Allgemeine Frontier-Modelle schränken i...

OpenAI Anthropic Benchmark
9
Mastodon discussion Oct 14

VETNET is an ecosystem of live benchmark datasets and evaluation frameworks that aims to accelerate AI-driven innovation...

VETNET is an ecosystem of live benchmark datasets and evaluation frameworks that aims to accelerate AI-driven innovation in animal science and veterinary medicine.Source: arXivhttp...

Benchmark
9
GitHub Trending repo Oct 14

polytutor-ai/polymarket-ai-trading-bot: AI trading bot for Polymarket prediction markets: an ML ensemble plus an OpenAI LLM for decisions, a leaderboard copy-trading bot, Rust services, a Postgres ledger, and a Python model server.

AI trading bot for Polymarket prediction markets: an ML ensemble plus an OpenAI LLM for decisions, a leaderboard copy-trading bot, Rust services, a Postgres ledger, and a Python mo...

OpenAI LLM Benchmark
38
Dev.to tutorial Oct 14

Your Financial Agent Passed Every Eval. Can You Defend Its Decision?

In audit, the opinion is the product, and an opinion is only as good as its basis. Being right isn’t...

Benchmark
33
Mastodon discussion Oct 14

📦 Fresh open weights on the leaderboard: LFM2.5-24B-A2B (Liquid)Context: 128k tokens · $0.05 in / $0.7 out per 1M · open...

📦 Fresh open weights on the leaderboard: LFM2.5-24B-A2B (Liquid)Context: 128k tokens · $0.05 in / $0.7 out per 1M · open weightsAll the latest models, tracked hourly:https://olud.a...

Benchmark
9
Mastodon discussion Oct 13

Show HN: Parsimony – an open-source benchmark for how much code AI models addhttps://parsimony.lasu.dev/#ai #open-source

Show HN: Parsimony – an open-source benchmark for how much code AI models addhttps://parsimony.lasu.dev/#ai #open-source

Open Source Benchmark
9
Hacker News discussion Oct 13

Show HN: Parsimony – an open-source benchmark for how much code AI models add

Show HN: Parsimony – an open-source benchmark for how much code AI models add

Open Source Benchmark
64
NewsData.io news Oct 13

Toptal Launches ExpertCrowd to Train AI with Vetted Domain Experts, Releases Frontier SWE Benchmark

SAN FRANCISCO, Oct. 14, 2026 /PRNewswire/ -- Toptal, the world's largest talent network of highly skilled domain experts, today announced the launch of ExpertCrowd, a platform for ...

Benchmark
21
Mastodon discussion Oct 13

AI agents: how can you assess reported speed gains and benchmark scores?https://podcast.aequitus.net/episodes/2026-10-04...

AI agents: how can you assess reported speed gains and benchmark scores?https://podcast.aequitus.net/episodes/2026-10-04-saturday-ai-agents-how-can-you-assess-reported-speed-gain-e...

Benchmark
9
Mastodon discussion Oct 13

📊 K2-V2 (Medium) scores are out, measured independently, not from its own team. GPQA 59.8%, MMLU-Pro 76.1%, but Humanity...

📊 K2-V2 (Medium) scores are out, measured independently, not from its own team. GPQA 59.8%, MMLU-Pro 76.1%, but Humanity's Last Exam drops to 4.4% — the gap between self-reported a...

Benchmark
9
Papers with Code paper Oct 13

Are We Testing Too Much? A Survey of Benchmark Compression for Efficient Evaluation of Large Language Models

Benchmarks are essential for evaluating and improving large language models (LLMs). Yet many widely used benchmarks are redundant, making evaluation unnecessarily expensive. Benchm...

Benchmark
21
Papers with Code paper Oct 13

OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding

With the rapid development of multimodal large language models (MLLMs), evaluating their video understanding capabilities has become increasingly important. Existing video understa...

Benchmark
21
Papers with Code paper Oct 13

MFVSR: A Multi-Style and Fine-Grained Benchmark for Video Subtitle Removal

Video subtitle removal (VSR) is an important video restoration task, yet existing evaluation remains limited by low-resolution datasets, fragmented test sets, and generic video-inp...

Benchmark
21
« Previous Page 9 of 70 (1661 items) Next »
AI Hub // AI Intelligence Platform // LIVE FEED // Impressum // Datenschutz © 2026
0 new articles available