
Let the LLM Talk, Let a Script Do the Math: A Three-Part Pattern for Decision Agents
A quick test You have two McDonald's coupons and can use only one: Spend 40, get 10...
15792 articles tagged with LLM
A quick test You have two McDonald's coupons and can use only one: Spend 40, get 10...
LLM-based decompilers can reconstruct variable names and logic — but recompiling the output often breaks binary equivalence. Interesting tradeoff: better readability, weaker semant...
US、冗談でしょう?Appleのスマートホームハブ「HomeView」は11月中旬に発売か|モデルは2つ、カラーは4色 https://netaful.jp/apple/0210757.html#Apple #LLM #news #bot
You face high cloud bills when you run powerful AI agents every day. Qwen3.5 gives you frontier-level...#agents #ai #llm #tutorial #software #coding #development #engineering #incl...
@cwebber Are you keeping a list of projects that are attempting to rewrite #copyleft codebases using LLM-gen-AI?I know about the #chardet situation, and while the project got delay...
Exploring the widening gap in LLM understanding and the latest shocks from OpenAI's finances.#ai #llm #coding #openai #software #development #engineering #inclusive #communityLLM C...
The Unplotted Instrument: Who Calibrates the Person Who Signs? Ask a room of experienced...#ai #llm #tools #productivity #software #coding #development #engineering #inclusive #com...

Proximal Policy Optimization (PPO) is widely used in reinforcement learning with verifiable rewards for language-model reasoning. While value evolution along trajectory characteriz...

Reinforcement learning with verifiable rewards (RLVR) is reshaping how large language models (LLMs) acquire reasoning capabilities, yet the optimizers used remain largely inherited...

Knowledge-based Visual Question Answering (VQA) requires reasoning that extends beyond visible image content, demanding external commonsense and factual knowledge. While recent wor...

Generative discovery in science requires coupling high-level scientific reasoning with the ability to generate samples respecting the structure of a design space. Yet these capabil...

Reinforcement learning with verifiable rewards (RLVR) typically uses small rollout groups per prompt, where repeated sampling from the same policy can yield highly similar trajecto...
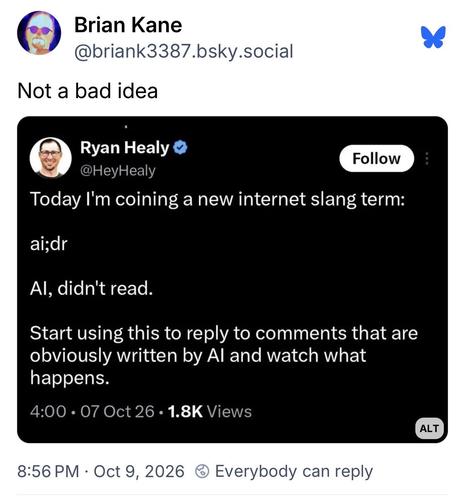
https://bsky.app/profile/briank3387.bsky.social/post/3mxibrjmka22o#AI #LLM
Most AI agent demos die on contact with production. Not because the model is weak, but because the...#ai #agents #llm #architecture #software #coding #development #engineering #inc...
Your AI Agent Has a Burn Rate — So I Benchmarked the Cost of a Correct Answer#kagglechallenge #ai #llm #opensource #software #coding #development #engineering #inclusive #community...
Why AI can't count the r's in strawberryhttps://youtube.com/shorts/BPGBULKf7FQ#AI #LLM #Tokenizer #llamacpp #Qwen3

I had been adding optimizations to mini-vllm-rs, my Rust LLM inference engine for macOS, including...
If you ask a language model to grade a text and also to count the words, add up the points and apply...#ai #llm #typescript #webdev #software #coding #development #engineering #inc...
The gap in shared understanding of LLM capability is wideninghttps://twitter.com/karpathy/status/2109361546505966046Comments: https://news.ycombinator.com/item?id=50047422#HackerNe...
The gap in shared understanding of LLM capability is widening
⚡ Llama.cpp tops today's Olud Pulse at 95/100 for local LLM runtimes, even with a -1 slip this week. What's dragging the score?https://olud.ai/tool/llama-cpp.html#OpenSource #AI #O...
No more Claude code reviews. https://www.bbc.com/news/articles/c6j9k1l72wkgo#llms #llm #ai

This is a submission for the Kaggle Benchmarking Challenge. What I Benchmarked I run a...
... 🤪https://www.bbc.com/news/articles/c6j9k1l72wkgo #AI #LLM